English
 Deutsch
 Polski
Freely Available LLMs Compared: Qwen, Gemma, Ministral, Llama and DeepSeek for DE, EN and PL

Contents
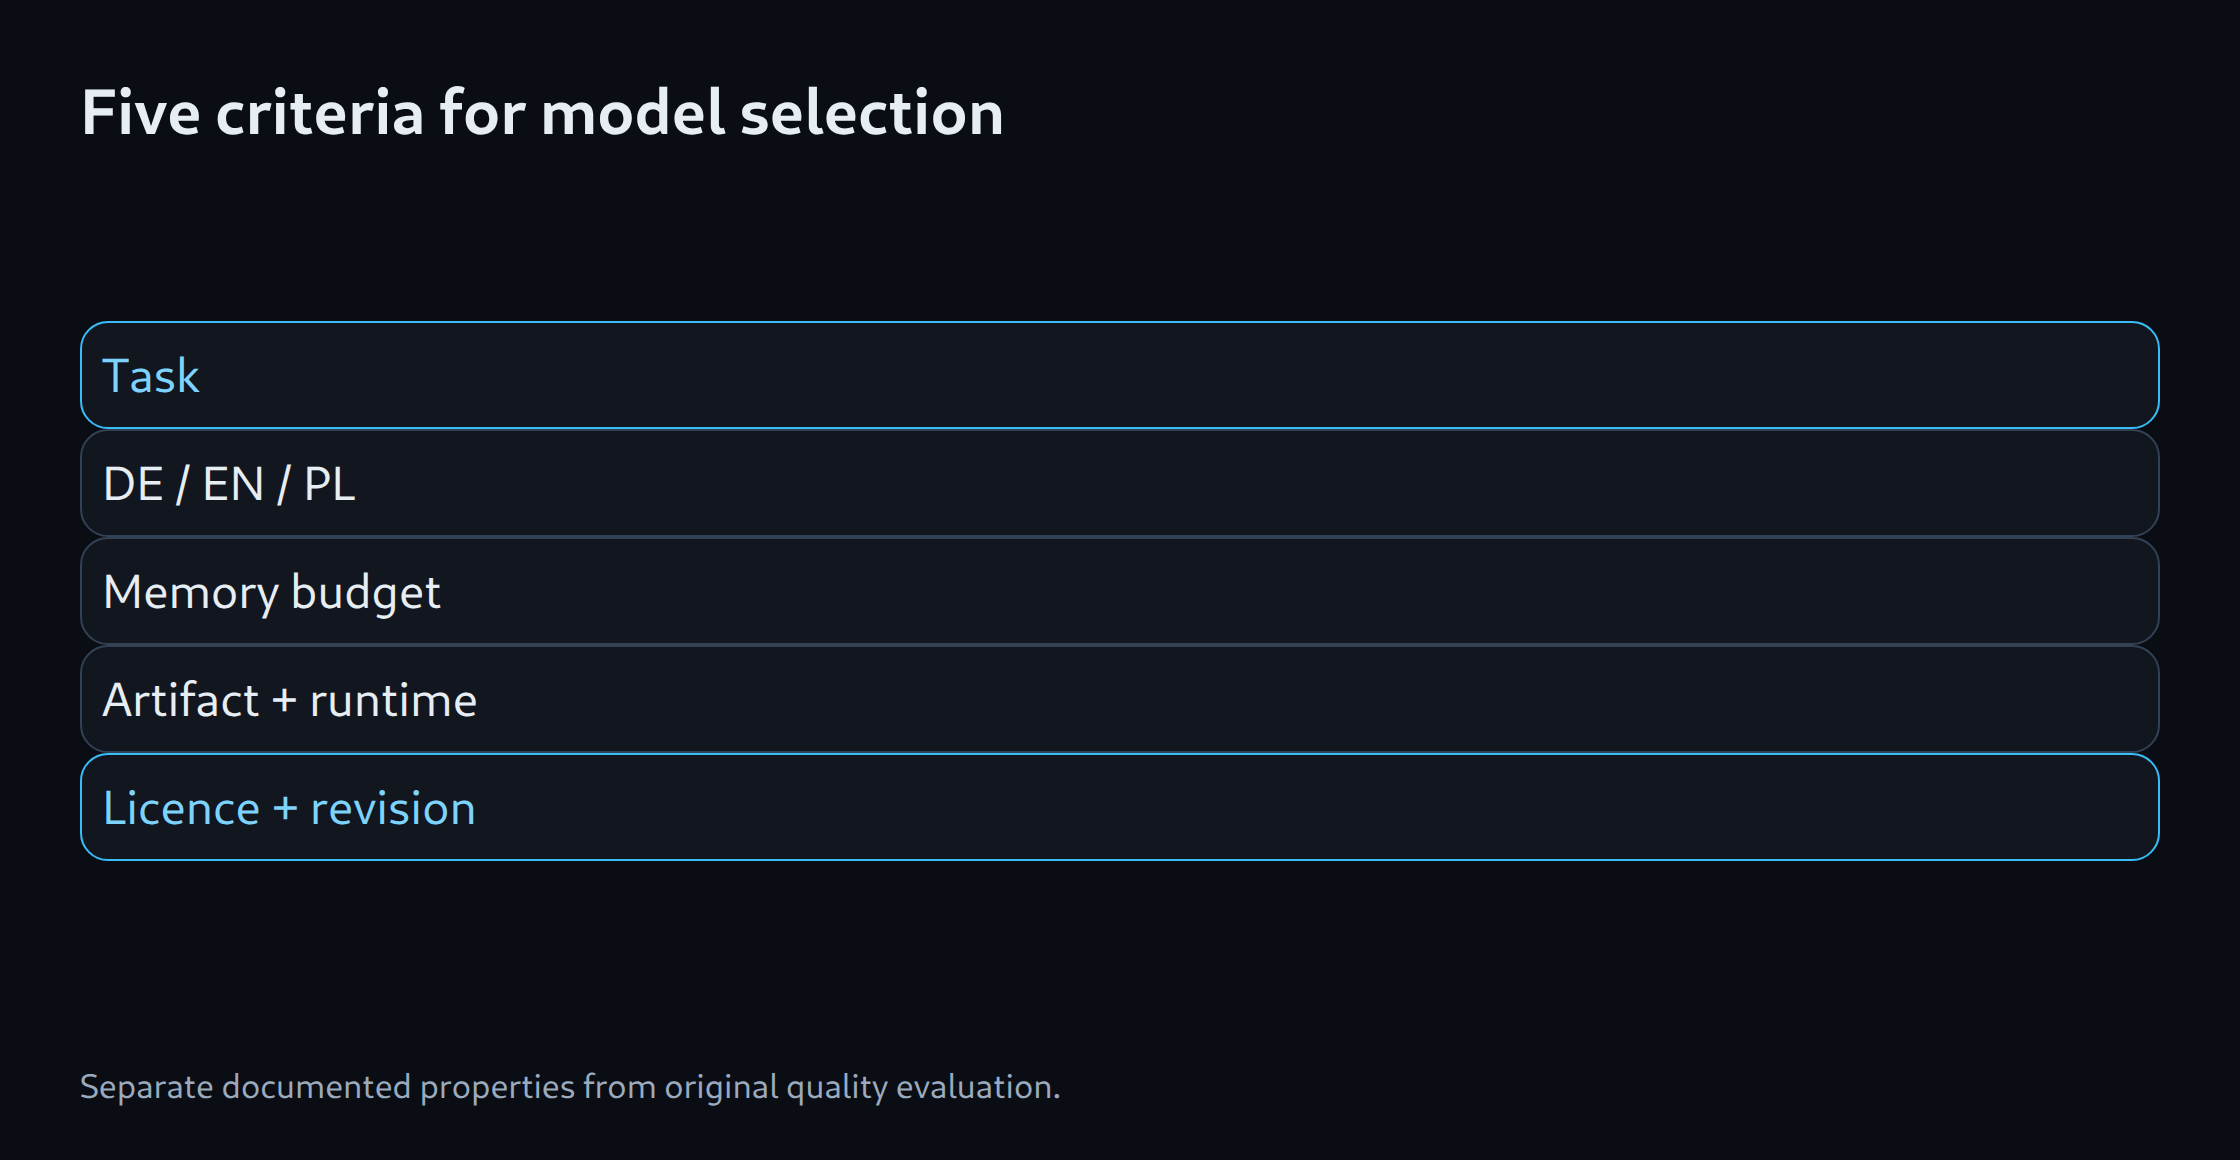
A freely available language model becomes useful locally only when task, language and hardware align. A strong general benchmark does not establish Polish writing quality or the memory requirements of a specific quantisation. Several comparison axes are therefore more useful than a single leaderboard.
This selection covers documented families and concrete candidates. It does not report an original quality benchmark. Download access, licensing and execution requirements receive separate treatment.
Candidate classes
| Candidate | Useful comparison | Specific check |
|---|---|---|
| Qwen3.5-9B | Compact general assistant | Hybrid architecture and backend |
| Gemma 4 Instruct | Matching size class and multimodality | Exact variant rather than family |
| Ministral 3 8B/14B | Local chat and structured output | Artifact precision and language test |
| Llama 3.3 70B Instruct | Larger reference model | Weights, context and licence |
| DeepSeek-R1-Distill | Reasoning in a suitable size class | Base model and output workload |
Availability is an incomplete description
Downloadable weights can still carry particular usage conditions. The specific model card and included licence determine the relevant terms. Derivatives can inherit conditions from their base model. A repository name does not settle that assessment.
Qwen3.5-9B and the selected Ministral 3 14B Instruct entry identify Apache 2.0. This does not assign the same licence to unrelated families or older generations. Base, instruction-tuned and reasoning variants also differ despite similar names.
DE, EN and PL need separate results
A useful task set includes summarisation, editing, JSON extraction, code analysis and answers grounded in a supplied document. Equivalent content is expressed naturally in all three languages. Assessment counts factual errors, omissions, format violations and unsupported additions.
A translated English benchmark does not replace a Polish language evaluation. A vendor list of supported languages does not demonstrate equal quality either. Names, inflection and neutral editorial style can produce distinct Polish failure patterns. Separate result columns preserve those differences.
Separate model-class and memory-budget comparisons
One comparison group keeps model class similar. Another keeps available memory fixed. This reveals whether a smaller higher-precision model or a larger more aggressively quantised model better serves the actual task.
Active parameters account for only part of an MoE model’s requirements. Total weights remain relevant to capacity. Llama 4 Scout and large current DeepSeek models do not become small desktop models merely because active-parameter counts sound smaller. Offloading further changes response behaviour.
A reproducible shortlist
Each result needs model ID, revision, quantisation, runtime, context, chat template and sampling settings. Reasoning output also requires a recorded generation limit. Otherwise a time comparison may simply measure longer answers. Image tasks remain a separate evaluation so that text comparisons do not mix different capabilities.
The existing memory estimator helps with initial selection. A small local quality test with verifiable expected answers follows. Only then does a defensible shortlist emerge for German, English or Polish. A universal ranking of all freely available models would be too coarse for that decision.
Memory planning for model selection: LLM VRAM estimator.
Related tools
Questions and answers
Does free availability automatically mean unrestricted use?
Download access and usage terms are separate properties. The licence and conditions of the specific model or derivative determine permitted use.
Is the model with the most parameters automatically best for Polish?
Parameter count and general benchmarks do not replace a Polish task evaluation. Language quality, error rate and compute budget require a combined assessment. Quantisation and chat templates can also affect results.
Sources
- Qwen: Qwen3.5-9B, offizielle Model Card
- Google DeepMind: Gemma 4
- Google: Gemma 4 31B, offizielle Model Card
- Mistral: Ministral 3 14B Instruct, offizielle Model Card
- Meta: Llama 3.3 70B Instruct, offizielle Model Card
- Meta: Llama 4 Scout, offizielle Model Card
- DeepSeek: R1 und Distill-Modelle
Sources checked: 5 October 2026.
Related articles