English
 Polski
When AI Reads Content: Pay per Crawl, Data Licensing or a Paid API?

Contents
An AI crawler can fetch content without creating a human visit or advertising revenue. Payment might therefore apply to access, agreed usage rights or prepared data. These are three different services.
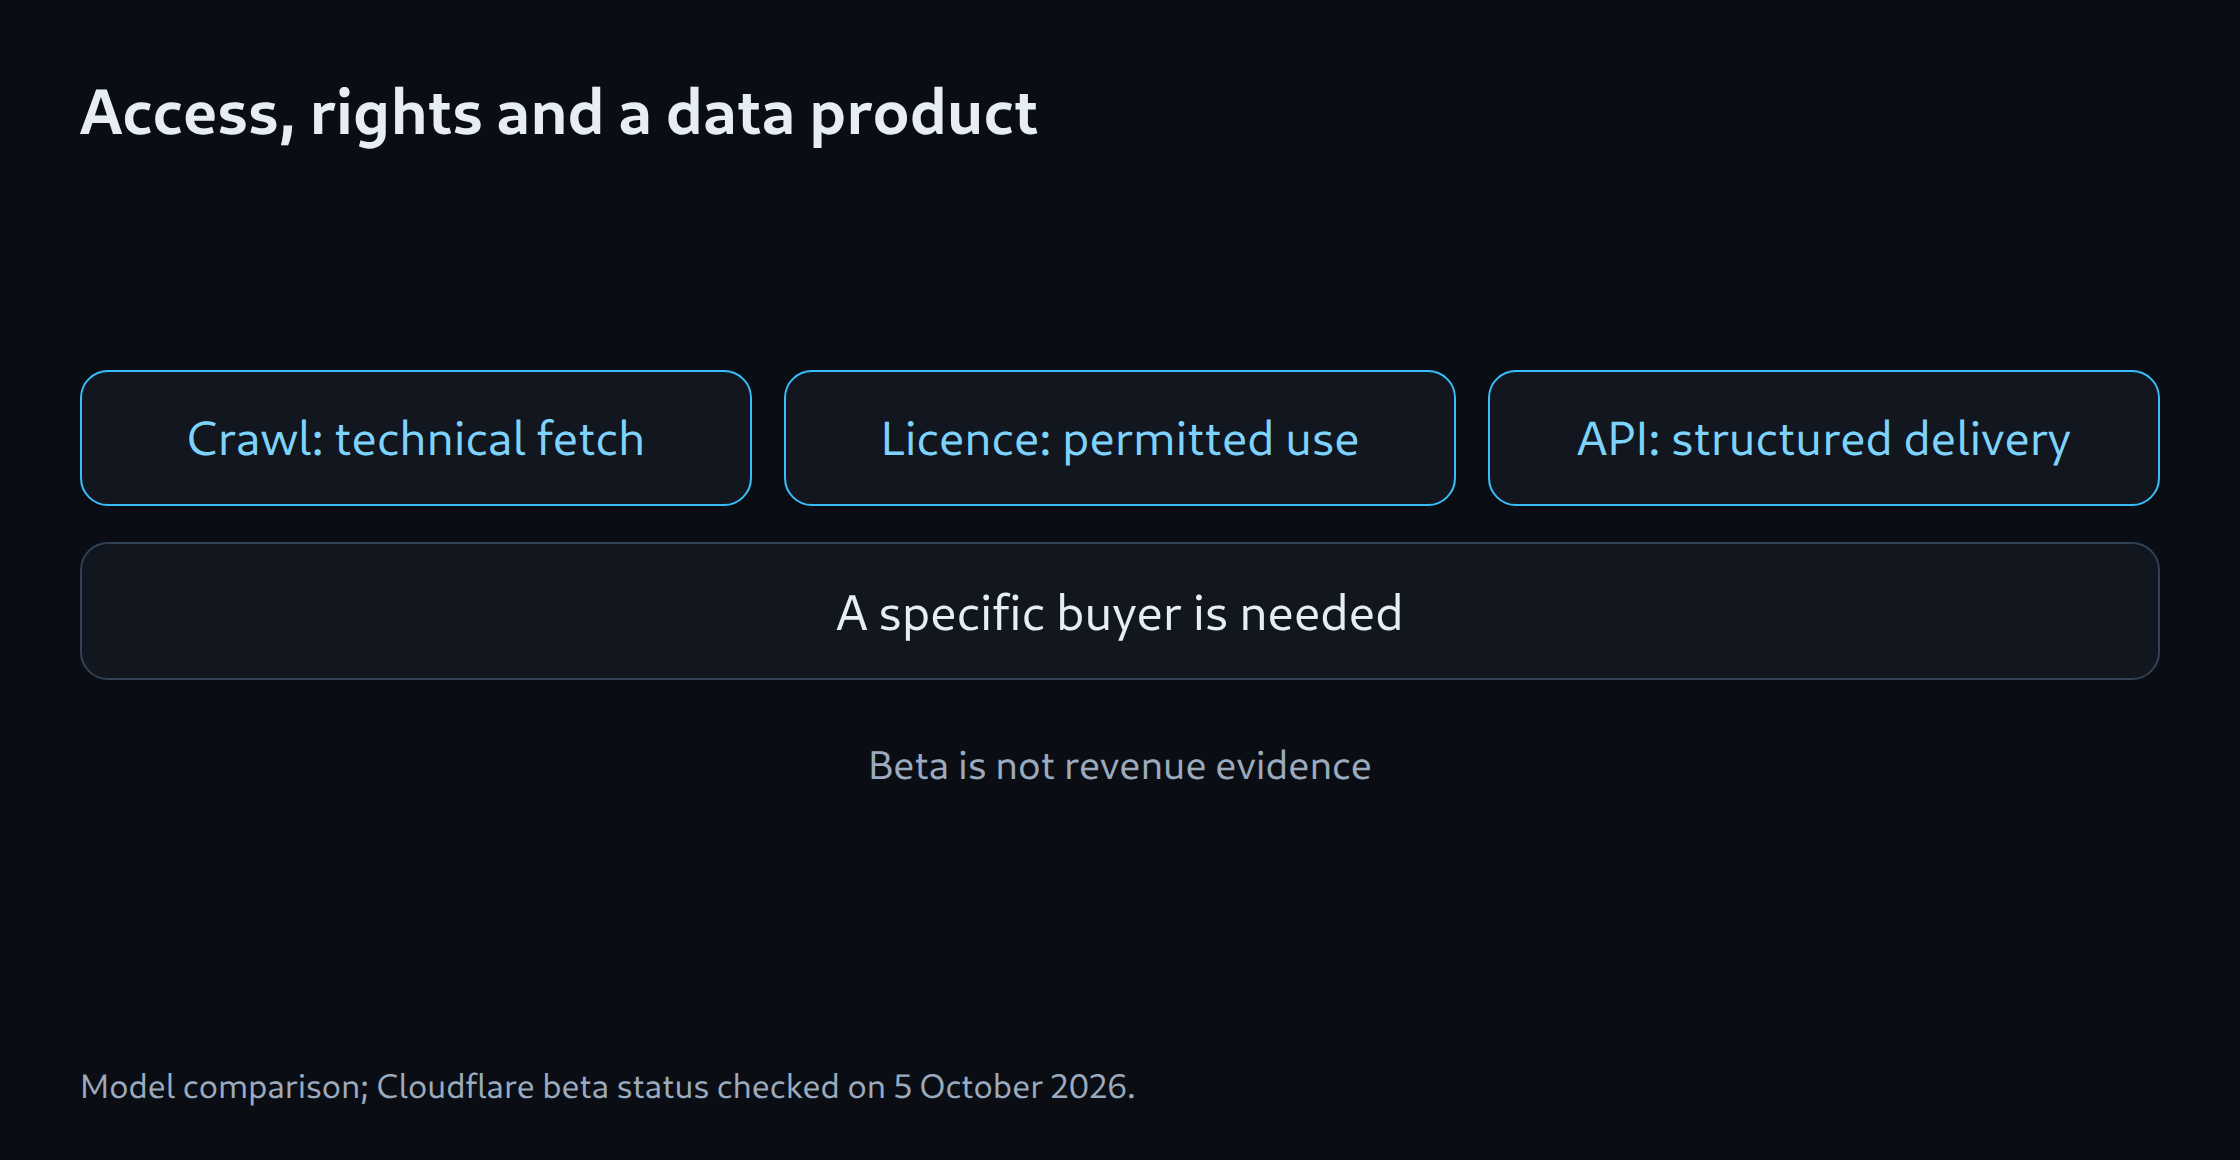
Three distinct layers
| Model | Service sold | Requirement |
|---|---|---|
| Pay per crawl | Paid technical access | Participating crawler willing to pay |
| Data licence | Agreed usage scope | Sufficient rights and a specific buyer |
| Paid API | Structured, dependable delivery | Quality, operation and integration |
Cloudflare’s described mechanism
Cloudflare documents a flow using HTTP 402 Payment Required and price information. Participating crawlers can express willingness to pay, and confirmed paid fetches are recorded. This is not automatic payment from arbitrary bots. [1]
On 5 October 2026, the public signup page still describes pay per crawl as a private beta. AI Crawl Control and paid access are distinct. Signing up does not establish activation or paying demand. [2]
Access is not a complete usage licence
A fetch describes transport. A licence can additionally define purpose, duration, redistribution, storage and permitted processing. Its scope needs a suitable agreement and sufficient rights. A price signal does not answer those questions.
Public articles may include third-party illustrations or embedded material. Permission to publish a page does not automatically include permission to relicense every component as data. Available material and rights need separate inventories.
When an API adds value
An API can deliver selected, structured and updated records. Buyers then pay for defined fields, versioning and dependable changes rather than access alone. A specialist catalogue with clear provenance differs from freely accessible HTML.
Authentication, limits, availability, corrections and support cost money. Export and deletion need to fit the offered usage. Without a specific integration customer, an API is technology rather than a demonstrated business.
A bounded business experiment
Original content, potential buyers and required data come first. A sample dataset and proposed usage scope support interviews. An access pilot would record accepted payments, revenue, operational costs and changes in other traffic. No crawl block or payment barrier was activated on this website.
A robots.txt file guides cooperating crawlers and does not protect confidential data. Search crawlers, AI crawlers and paying data customers need separate policies. Blanket blocking can affect activities beyond the intended product. [3]
The most credible route has an identifiable buyer and bounded service. Pay per crawl is an interesting infrastructure hypothesis; licensing and APIs remain separate business models.
Related tools
Questions and answers
Does every AI crawler automatically pay?
No. The described protocol requires participation and willingness to pay.
Was pay per crawl enabled on this blog?
No. The article describes models; no blocking or payment rules were introduced.
Sources
- Cloudflare: Introducing pay per crawl
- Cloudflare: Pay per crawl private beta
- Google: Robots.txt limitations
Sources checked: 5 October 2026.
Related articles