English
 Deutsch
 Polski
WAN Failover: What Happens to Open Connections When the Line Switches

Contents
Failover is usually described in seconds: the health check notices, the router switches, the line is back. That description is accurate about the line and silent about everything that was using it, which is the part anyone in the middle of a call will notice first.
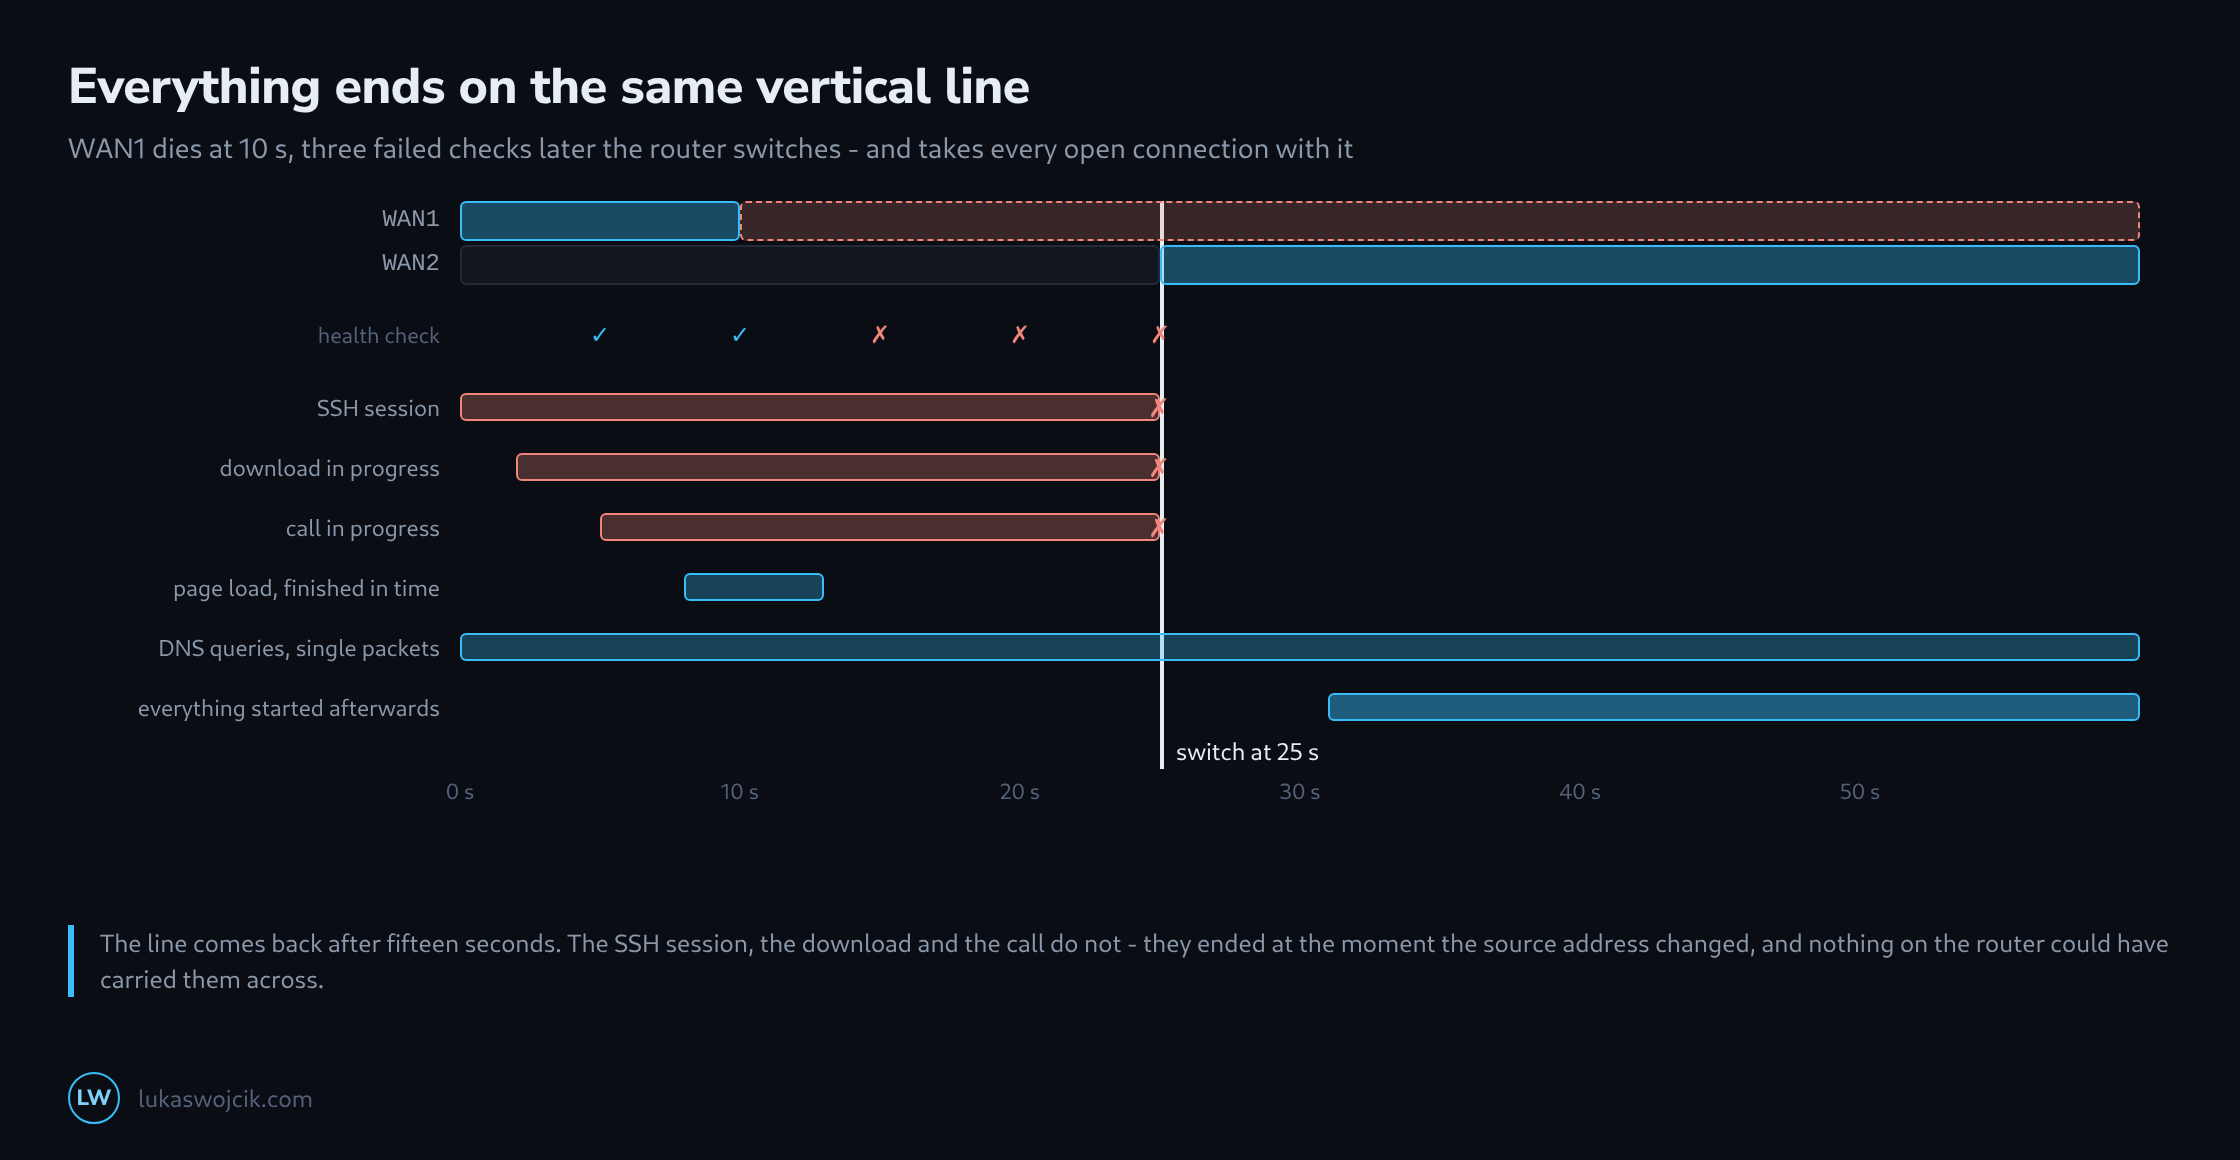
What happens at the moment of the switch is not a brief interruption of existing connections. It is the end of them.
Why Every Connection Dies
A TCP connection is identified by four values: both addresses and both ports. Traffic leaving through WAN1 carries WAN1’s public address, and the server on the other side has that address in its half of the connection.
After the switch the same traffic leaves through WAN2 and arrives with a different source address. To the server that is not the same connection – it is packets belonging to nothing, which get a reset or get dropped. The router cannot help: the translation state that mapped the internal connection to WAN1’s address belongs to an interface that is down.
Which is why the phrase to avoid is seamless failover on this class of hardware. What is seamless is the availability of a path. Sessions are not carried across it, and no timer setting changes that.
How Long the Switch Actually Takes
The visible part is the health check arithmetic – the interval multiplied by the number of failures tolerated. The invisible part comes before it: the line can be dead for almost a full interval before the first check even notices, because the check that just succeeded ran a moment before the failure.
worst case  = interval × (failures + 1)
typical     = interval × (failures + 0.5)

interval 5 s, 3 failures
  best   15 s
  typical 17.5 s
  worst  20 s

plus the time the applications need to notice their sessions are gone,
which for a TCP timeout is far longer than any of the above
The last line is the one that decides what a person experiences. The router is back after fifteen seconds; a download that has not yet realised its connection is dead sits in a TCP retransmission timeout for considerably longer, and a browser tab looks frozen the whole time.
What Survives and What Does Not
| Traffic | Survives? | Why |
|---|---|---|
| SSH, database connections | no | long-lived TCP, tied to the address pair |
| Downloads over HTTP/1.1 and HTTP/2 | no | TCP; restarts from the beginning without range requests |
| HTTP/3 (QUIC) | often | a connection ID identifies the session, not the address |
| A call in progress | no | the media stream is addressed to the old public address |
| DNS queries | yes | single packets, retried as a matter of course |
| A VPN tunnel | briefly gone | notices and rebuilds itself, carrying its own sessions |
The QUIC row is the genuine exception and worth knowing about, because it is quietly becoming the common case: a connection identifier that does not depend on the address is exactly the property that makes a path change survivable, and both ends have to support it.
The VPN row points at the one arrangement that helps in practice. A tunnel that reconnects by itself turns one failover into one reconnect, and everything inside the tunnel sees a short pause rather than a dead connection – because inside the tunnel the addresses never changed.
Switching Back Costs the Same Again
The switch back to the primary line is a second switch, with a second round of dead sessions. That is the reason the two timers should not be symmetric: switching over quickly limits the outage, switching back slowly avoids paying the price twice for a line that is not yet stable.
A flapping connection with equal timers is the worst case in the whole subject. Every flap costs two rounds of broken sessions, and a line that flaps every few minutes is materially worse than a line that is simply down – because a line that is down fails over once and then stays put.
What Can Be Done About It
Not much at the router, and that is worth saying plainly rather than tuning settings in the hope that one of them is the trick. Three things do help.
Distinct health check targets on the two uplinks, so that an outage at the target is not mistaken for an outage of both lines. A return timer several times longer than the failover timer, so that flapping costs one switch instead of ten. And, for anything that genuinely must not drop, a tunnel that survives the path change and carries the sessions inside it.
Beyond that the honest position is to plan for the interruption rather than to deny it: know that the calls will drop, that the backup will restart, and that the fifteen seconds in the configuration are the smaller half of what the outage actually costs.
Questions and answers
Why does an IP phone stay unreachable for new incoming calls after the switch?
For two reasons, both of which last longer than the switch itself.
- The registration. The phone registers with the provider under the public address its packets arrive from, and the provider sends incoming calls to exactly that address. After the switch the provider still holds WAN1’s address, and that remains so until the phone registers again; how long that takes depends on the configured interval.
- The translation state in the router. Phones keep their connection to the provider open with small packets at regular intervals, and each of these packets refreshes the entry that sent them out through WAN1. An entry that never goes quiet never expires. Depending on the router, it therefore stays tied to the failed line, and the packets keep going nowhere although WAN2 has long been ready.
Against the second reason, many routers offer a setting that clears the existing states when the active line changes. In a failure, this costs nothing that would not be lost anyway, because those entries point at a line that is down. The effect of the first reason is limited by a shorter registration interval on the phone, at the cost of more frequent registrations.
Can a shorter check interval make the switch faster?
Yes, by the same formula: at one second and three failures, it takes three to four seconds instead of fifteen to twenty. The price is sensitivity, because three lost probes in a row can occur on a fully loaded line without any outage, and every false switch costs the same two rounds of broken sessions as a real one.
Does it help to use both lines at once rather than keeping one as a standby?
Partly. Load balancing as usually implemented assigns each connection to one line, not each packet, because otherwise the same connection would arrive from two source addresses. When a line fails, only the connections that were running over it die, and the rest carry on. The switch itself remains as abrupt as the article describes; it simply hits fewer sessions.
In return, a new problem appears in normal operation. Consecutive connections from the same device can leave through different lines, and a service that ties a login to the source address suddenly sees two addresses and ends the session. Routers solve this with a setting, often called “sticky connections”, that pins all connections from one internal device to the same line for a while. The load is then distributed by device rather than by connection.
Related articles