English
 Deutsch
 Polski
Bot Detection: IP Lists and Cryptographic Signatures Compared

Contents
Apple enlarged the address pool behind Applebot during August 2026. The reported figures are a jump from around 2,400 addresses across twelve prefixes to roughly 7,056 across thirty-three, and the published range list is described as still incomplete. Every site that verifies that crawler against a stored copy of the list had to fetch a new one, or quietly started treating a legitimate crawler as an impostor.
That is not a flaw in this particular release. It is the defining property of proving identity by address, and it is worth setting against the alternative rather than complaining about it.
The address proof, and its self-updating variant
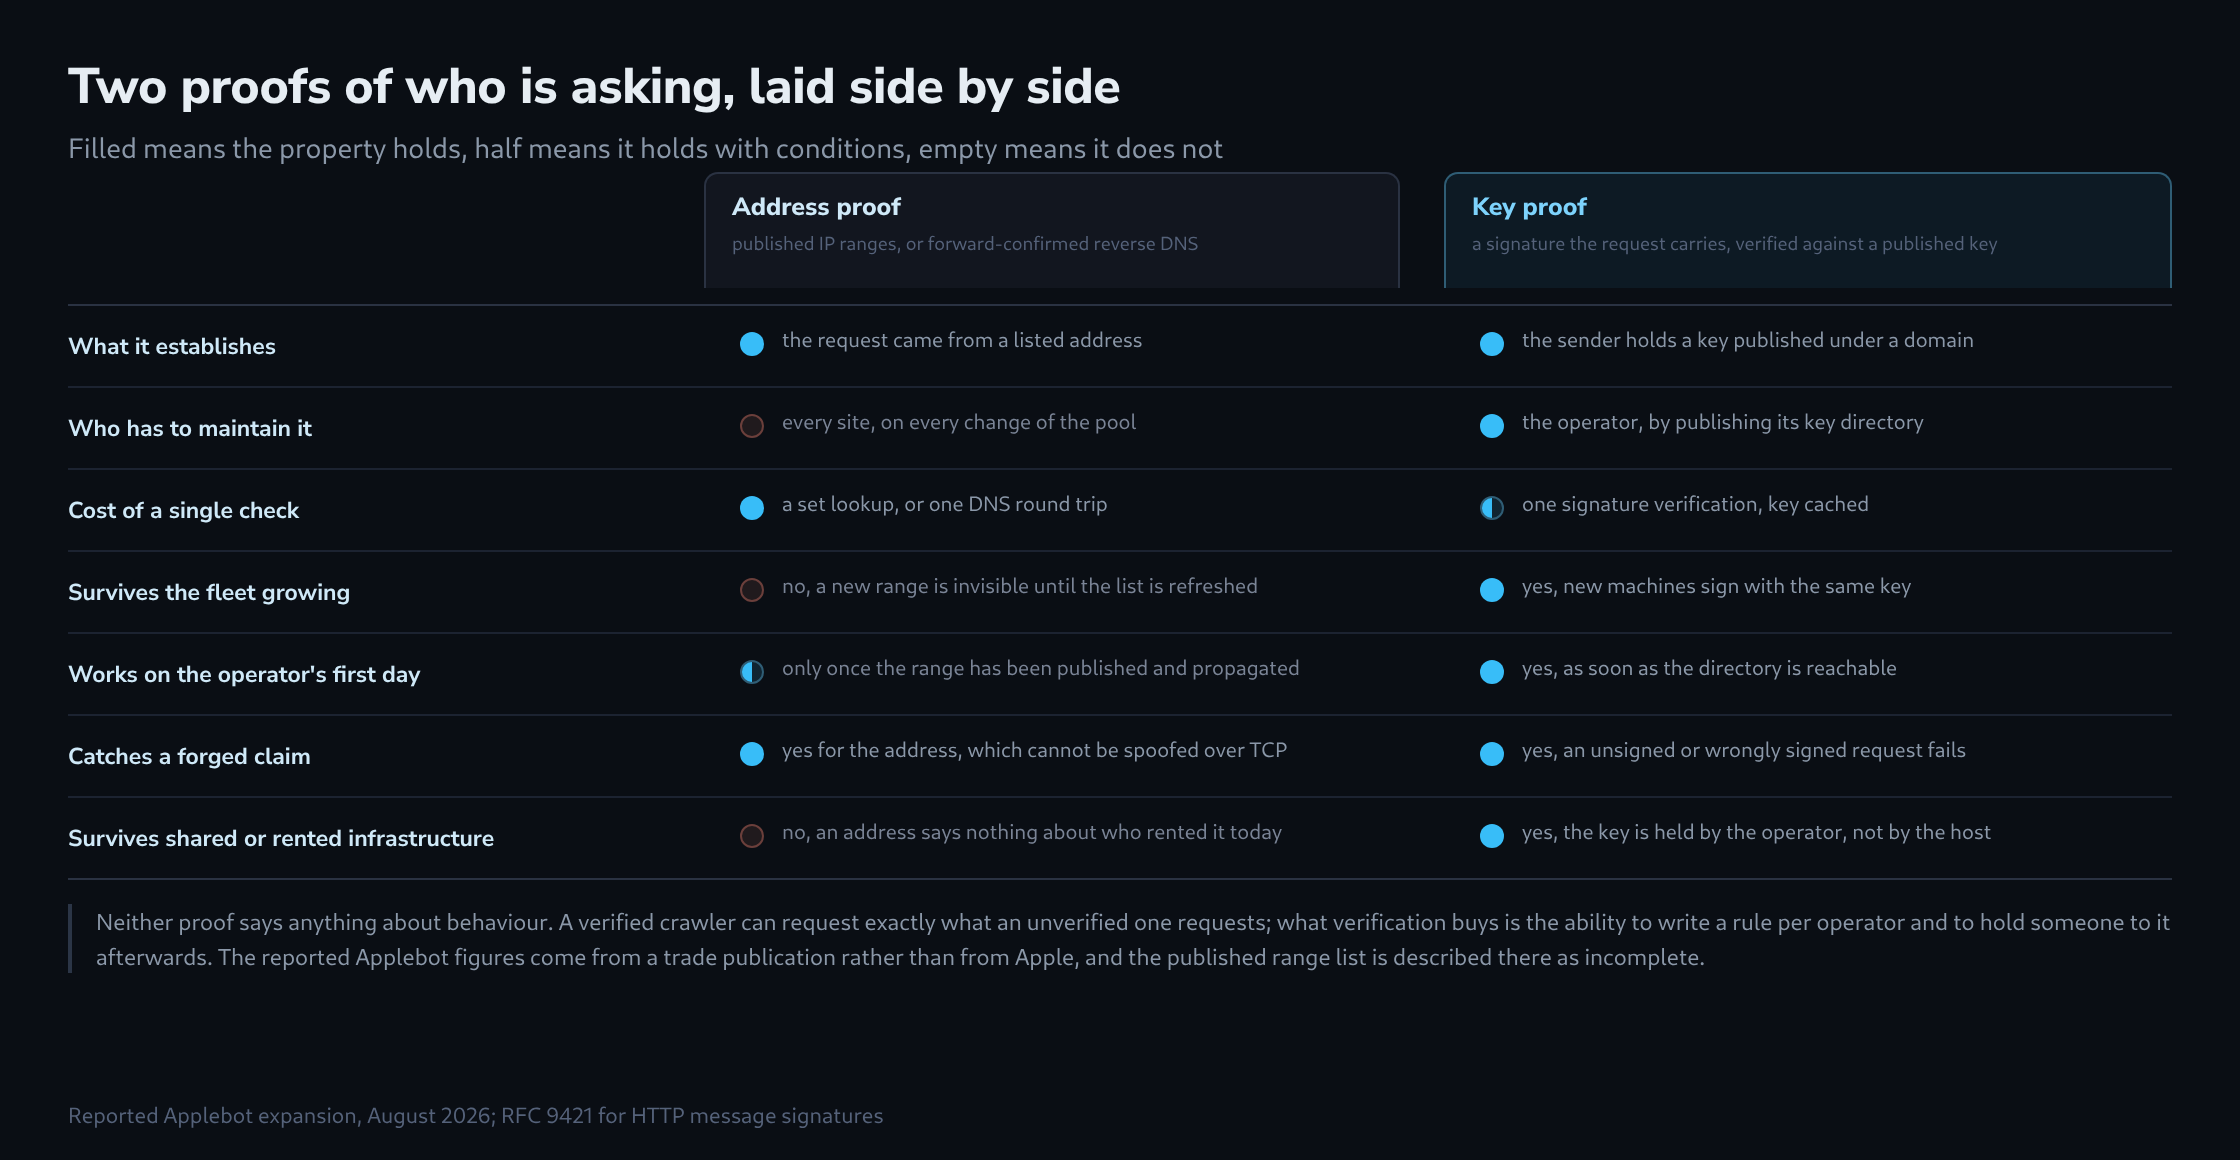
The simplest form is a list of ranges the operator publishes and every site downloads. It works because a source address cannot be forged across a completed TCP handshake, which makes it a genuine proof of origin rather than a claim.
Forward-confirmed reverse DNS is the same proof with the maintenance moved. Instead of holding the ranges, a site resolves the address backwards, then resolves the resulting name forwards again and checks that it lands on the address it started from.
address in the request        17.241.75.12

  reverse lookup             -> some-host.applebot.apple.com
  suffix check               ends in a domain the operator owns
  forward lookup             -> 17.241.75.12
  compare                    same address, so the claim holds

  fails safe: a forged reverse record does not survive the
  forward lookup, because the attacker does not control the
  operator's forward zone
This variant costs one or two DNS round trips per new address, cached afterwards, and it does not go stale when the pool grows. It remains an address proof, though, with everything that implies.
What an expansion actually costs
A pool that nearly triples produces two failure modes, and only one of them is loud. The loud one is a crawler being blocked, noticed within a day because content stops being indexed. The quiet one is worse: a site that treats unverified traffic as ordinary human traffic now has several thousand addresses’ worth of crawler activity sitting in its analytics as sessions.
Neither failure announces itself as a list problem. Both look like something else, which is why the refresh cadence for any published range list belongs in a scheduled job rather than in someone’s memory.
The key proof
The other approach moves the evidence into the request. The operator holds a key pair, publishes the public half under a domain it controls, and signs each outgoing request; the site verifies the signature against the published key. HTTP message signatures, standardised in RFC 9421, are the mechanism, and Web Bot Auth is the profile of it aimed at agents.
Its advantage over an address is structural. A key follows the operator, not the machine, so new capacity signs with the same key on the day it comes online and no list anywhere needs touching. It also survives rented infrastructure, where an address genuinely cannot help: the address block belongs to a hosting provider, and knowing that tells nobody who is renting it this month.
The cost is that it only exists where an operator has chosen to implement it. An address proof works against every crawler that publishes ranges, which is most of the established ones; a key proof works against the subset that signs, which today is small.
Which one, and when
In practice they are not competitors. An address check answers a question a signature cannot: whether traffic claiming to be a well-known crawler really originates where that crawler lives. A signature answers a question an address cannot: which of several operators sharing a data centre actually sent this.
The sensible arrangement runs the address check first, because it is cheap and covers the established crawlers, and accepts a valid signature as an independent second path for operators that offer one. What neither of them provides is a judgement about what the request is for. Both establish who is asking. Nothing in either proof speaks to what happens with the answer.
Questions and answers
Is checking the user agent not enough?
No. Every client sets its own user agent; it is the claim to be verified, not the proof of it. What it is good for is choosing the right check: traffic claiming to be Applebot is checked against Apple’s ranges or host names.
What changes when a CDN or reverse proxy sits in front of the server?
The address the server sees then belongs to the service in front of it. The completed TCP handshake now only proves that the request came from the CDN; the crawler’s address sits in a header such as X-Forwarded-For, which the service adds. Both checks, whether by range list or by reverse and forward lookup, have to start from that address, otherwise they verify the CDN.
That makes protection against forgery a precondition: the header is only as trustworthy as whoever sent it. A client that reaches the server directly can fill X-Forwarded-For with any address from Apple’s ranges and will then pass every address check. The header may therefore only be evaluated when the connection itself comes from the CDN’s published ranges, and where it holds several entries, the one that counts is the last, added by the CDN itself, not the first.
Many CDNs also run crawler verification themselves and expose the result in their rules. That is convenient, but it merely hands the question of whether an enlarged pool is already recognised over to the provider.
Can a valid signed request be sent again by a third party?
In principle, yes, for instance when the operator of another site passes a signed request addressed to it on to someone else’s site. A signature proves who signed the message, not who is sending it right now. RFC 9421 therefore provides parameters that narrow down replay: created and expires for the period in which the signature is valid, and nonce for a value that is accepted only once. Which parts of the request are signed can also be specified, such as the target host through the @authority component; a signature made for another domain then fails the check.
How much of this a site demands is its own decision at verification time. A short validity keeps the window small; a stored list of nonces already seen closes it, but costs storage and, with several servers, a shared store.
Why does crawler traffic show up in some analytics and not in others?
Because the tools count at different points. Server logs record every request; a JavaScript-based tool only records visits in which the script runs and sends its hit. Many crawlers fetch only the HTML and never show up there; others render pages including JavaScript and can then produce sessions.
Then there is built-in filtering. GA4 automatically excludes traffic from known bots and spiders; this cannot be switched off, and GA4 does not show how much was excluded. Anything not on that list counts as an ordinary visit. Server-side counting without verification counts everything anyway.
For the quiet failure mode, this means that the first to be affected are server-side counts and log analyses that subtract verified crawlers and treat everything else as human. There, a stale range list makes every new Applebot prefix look like a person. A sudden rise in supposedly human requests from the new prefixes is therefore the first reason to suspect the stored list.
Practical check: investigate GA4 traffic groups
The GA4 traffic review tool groups reported data by browser, operating system, country and session source/medium. It shows explicit cues instead of a bot probability: no engaged sessions, zero average duration, missing dimensions or an automation-related browser name. A configurable minimum keeps small groups from receiving these cues, while retaining their rows in the output.
These observations do not authenticate a crawler. A campaign, consent behaviour, incomplete collection or internal testing can produce similar patterns. Country and Direct traffic are not evidence of automation. The exported CSV can support a comparison with server or CDN logs, but this report contains neither client IP addresses nor verified signatures. No data is excluded or changed.
Google automatically excludes known bot traffic and does not disclose its excluded count in GA4. A result without matching rules therefore means only that the selected checks found nothing in the returned rows. Sources: Google’s known-bot exclusion and Data API schema.
Related articles