English
 Deutsch
 Polski
Self-Hosted Large Language Model (LLM) with Ollama Behind an Auth Proxy

Contents
Sending proprietary corporate documents, customer records, and source code to public Large Language Model (LLM) APIs such as OpenAI, Anthropic, or Google Gemini creates severe data sovereignty risks and potential GDPR violations. Hosting open-weight LLMs—such as Llama 3.1, Mistral, or CodeLlama—on internal enterprise hardware guarantees complete data isolation. However, because the popular inference server Ollama exposes its REST API on port 11434 without native authentication, deploying it safely inside an enterprise network requires an architectural wrapper: an Nginx reverse proxy enforcing strict authentication and TLS encryption.
1. Architectural Framework: Secure Edge Inference Pipeline
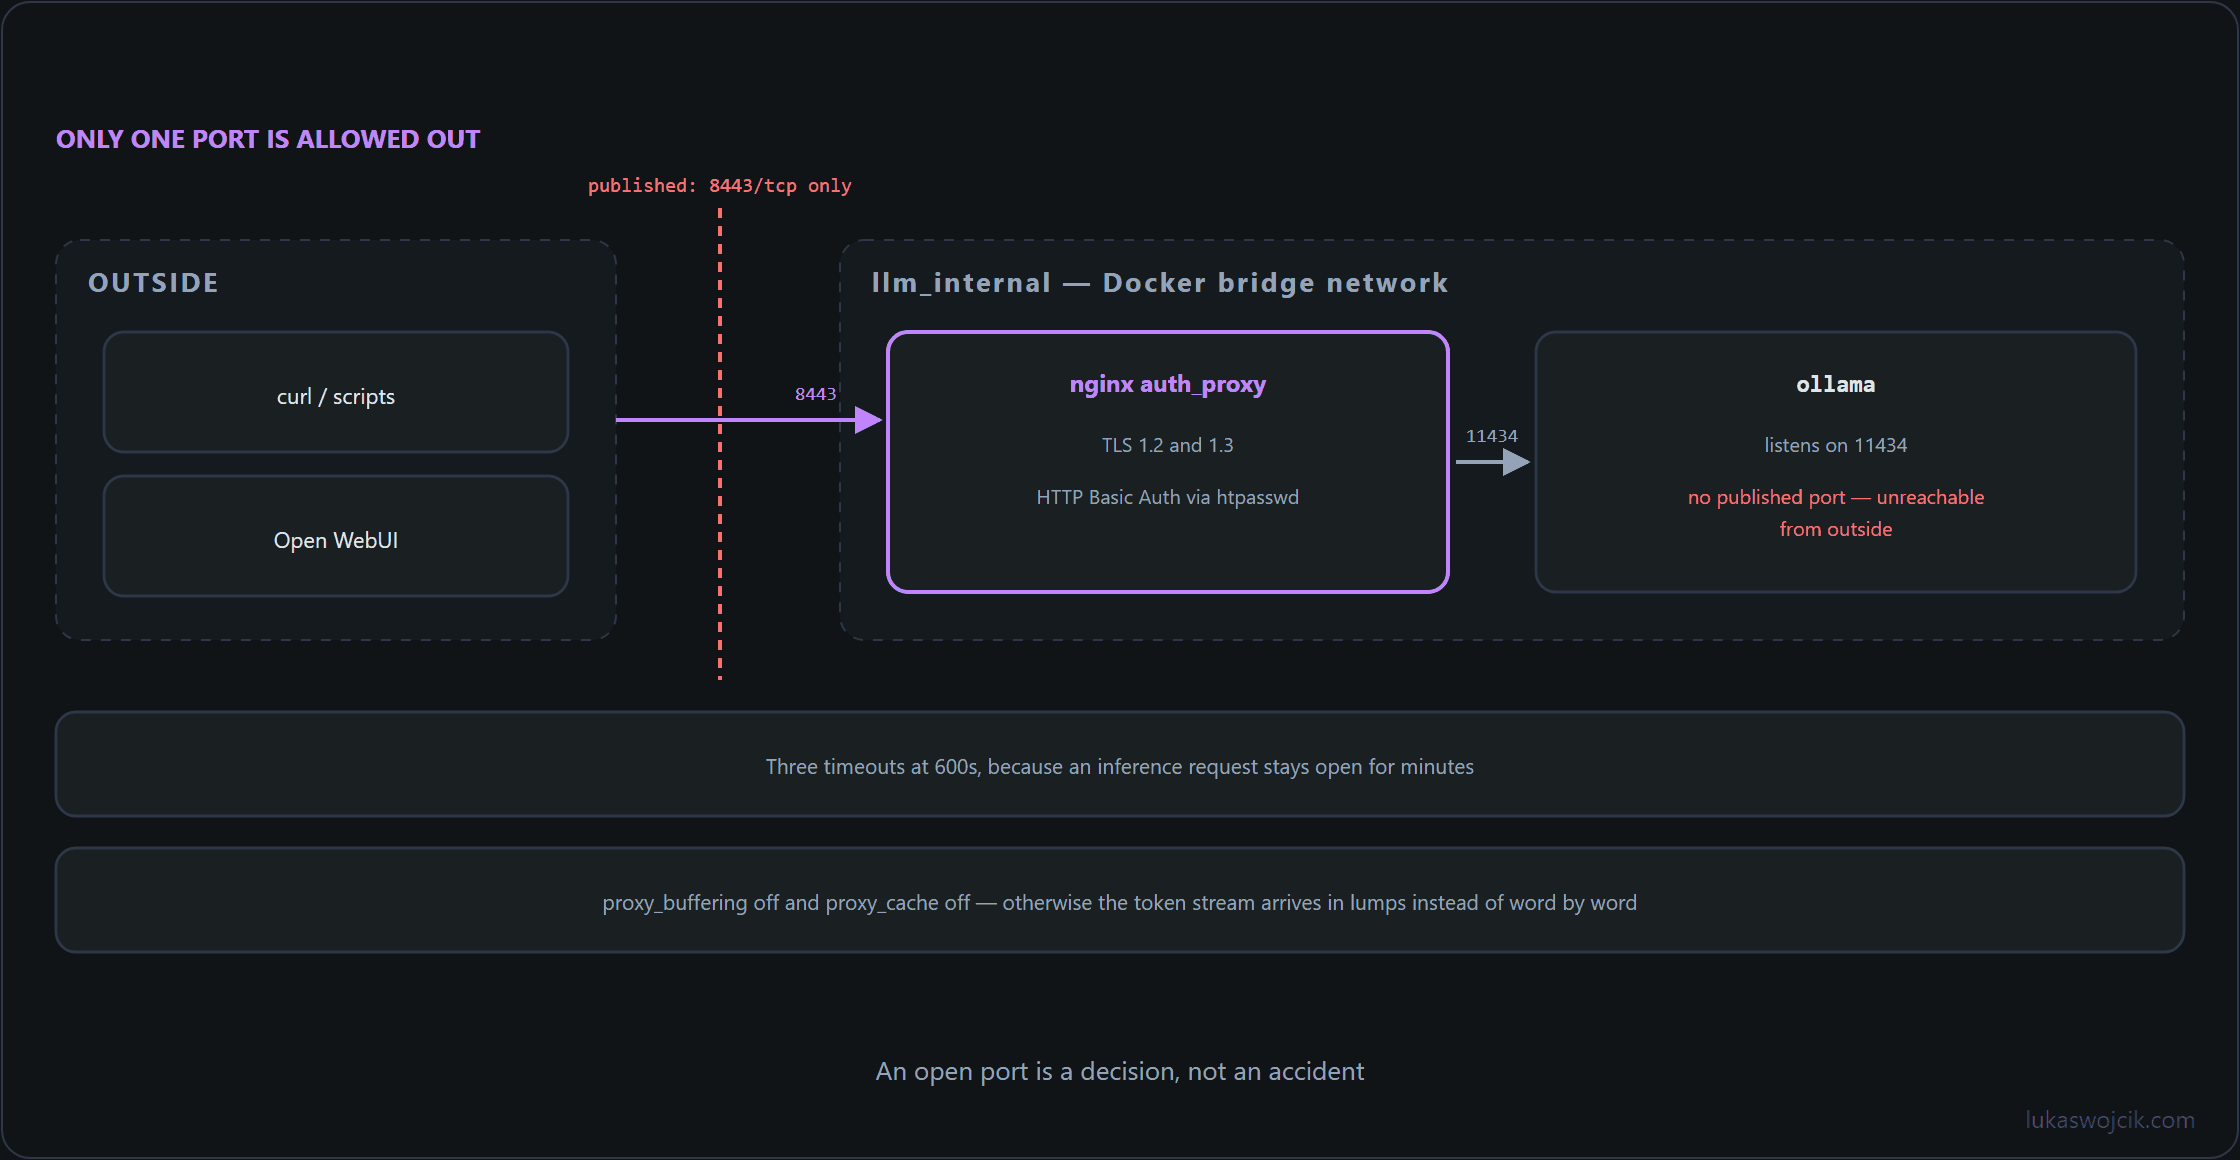
An enterprise-grade local LLM deployment decouples model execution from network exposure by layering three isolated services within a containerized environment:
- Ollama Inference Backend: Executes open-weight LLM weights using NVIDIA GPU acceleration (via NVIDIA Container Toolkit) or high-thread CPU quantization, bound strictly to internal container network interfaces.
- Nginx Authentication & TLS Reverse Proxy: Acts as the single entry point, intercepting all HTTP requests, terminating SSL/TLS encryption, and validating HTTP Basic Authentication credentials before proxying requests to Ollama.
- OpenAI-Compatible Frontend / Scripts: Internal web UIs (such as Open WebUI) or automated Python scripts interact with the secured endpoint using standard OpenAI SDK syntaxes without ever bypassing the proxy security layer.
2. Step-by-Step Container & GPU Provisioning
To launch Ollama alongside a dedicated Nginx reverse proxy, deploy the following production-ready docker-compose.yml file configured for GPU passthrough and isolated networking:
services:
  ollama:
    image: ollama/ollama:latest
    container_name: enterprise_ollama
    restart: always
    environment:
      - OLLAMA_HOST=0.0.0.0
      - OLLAMA_ORIGINS=*
    volumes:
      - ./ollama_data:/root/.ollama
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]
    networks:
      - llm_internal

  auth_proxy:
    image: nginx:alpine
    container_name: ollama_auth_proxy
    restart: always
    ports:
      - "8443:443"
    volumes:
      - ./nginx.conf:/etc/nginx/nginx.conf:ro
      - ./certs:/etc/nginx/certs:ro
      - ./htpasswd:/etc/nginx/.htpasswd:ro
    depends_on:
      - ollama
    networks:
      - llm_internal

networks:
  llm_internal:
    driver: bridge
3. Step-by-Step Nginx Auth Proxy Configuration
To restrict API access exclusively to authorized enterprise applications, Nginx is configured to require HTTP Basic Authentication. The following nginx.conf script enforces authentication and manages streaming timeouts for large LLM inference responses:
events {
    worker_connections 1024;
}

http {
    upstream ollama_backend {
        server ollama:11434;
    }

    server {
        listen 443 ssl;
        server_name llm.internal.domain;

        ssl_certificate /etc/nginx/certs/server.crt;
        ssl_certificate_key /etc/nginx/certs/server.key;
        ssl_protocols TLSv1.2 TLSv1.3;

        # Enforcing HTTP Basic Auth (Generate via: htpasswd -c ./htpasswd api_user)
        auth_basic "Enterprise LLM Secure Gateway";
        auth_basic_user_file /etc/nginx/.htpasswd;

        # Mandatory timeout extensions for long-running streaming inference
        proxy_read_timeout 600s;
        proxy_connect_timeout 600s;
        proxy_send_timeout 600s;

        location / {
            proxy_pass http://ollama_backend;
            proxy_set_header Host $host;
            proxy_set_header X-Real-IP $remote_addr;
            proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
            proxy_set_header X-Forwarded-Proto $scheme;

            # Streaming support for Server-Sent Events (SSE)
            proxy_buffering off;
            proxy_cache off;
        }
    }
}
4. Step-by-Step Script & Web UI Verification
Once the proxy is active, the inference engine can be queried safely via standard scripts or integrated into chat UIs:
- Downloading Models: Execute the initial model pull inside the container via Docker command-line execution:
docker exec -it enterprise_ollama ollama run llama3.1 - Python API Verification: Send an authenticated HTTPS REST request to the proxy using HTTP Basic credentials or authorization headers:
curl -k -u "api_user:SecretPassword123" https://localhost:8443/api/generate -d '{"model": "llama3.1", "prompt": "Summarize the company privacy policy.", "stream": false}' - Connecting Open WebUI: Deploy the
open-webuiDocker container on the same network and assign the endpoint environment variable:OLLAMA_BASE_URL=https://api_user:SecretPassword123@auth_proxy:443
5. Summary & Architectural Value
What this tutorial achieves: The tutorial shows how to deploy a self-hosted, GPU-accelerated server for open-weight LLMs with Ollama and protect it with an Nginx reverse proxy that handles authentication and SSL/TLS.
Resulting value: A private, high-performance “ChatGPT”-equivalent is established for corporate workflows, internal software scripts, and employee web UIs without any data leakage to external commercial AI APIs. Complete data sovereignty and GDPR compliance are guaranteed, while mandatory authentication headers prevent unauthorized network access to the inference compute resources.
Questions and answers
Why does the proxy set 600-second timeouts, and do they apply to the whole response?
Not to the whole response. According to the nginx documentation, proxy_read_timeout only limits the time between two successive read operations; the default is 60 seconds. With streaming, every generated token brings a new piece of the response and the timer starts again. Operation without streaming is the critical case, as in the curl example with "stream": false. Ollama then sends only the finished answer. If the model runs on the CPU, or if Ollama first has to load it into memory on the first request, more than 60 seconds can pass before that, and without a longer timeout nginx aborts with status 504.
For proxy_connect_timeout, on the other hand, the high value achieves nothing. The connection to a container on the same Docker network is established in a fraction of a second, and according to the documentation this timeout usually cannot exceed 75 seconds anyway.
Can Ollama be reached past the proxy with OLLAMA_HOST=0.0.0.0?
Not from outside with this Compose file. The variable makes Ollama listen on all of the container’s interfaces, which is necessary for the proxy to reach the service at ollama:11434. Only the proxy’s port 8443 is published, however, because the ollama service has no ports entry.
Two changes would undermine the protection:
- An entry such as
"11434:11434"on theollamaservice. Docker publishes such ports through its own iptables rules, which according to the Docker documentation bypass firewall rules set with ufw. If the port is needed on the host for testing,"127.0.0.1:11434:11434"limits it to the host itself. - Further containers on the
llm_internalnetwork. Within that network, every container reaches Ollama directly and without authentication, including Open WebUI if it runs there. Going through the proxy is then a setting, not a barrier. This can be ruled out with a network of its own for Ollama and the proxy only, while the proxy also joins a second network through which Open WebUI reaches it.
Can the proxy be used with the OpenAI SDK?
Not with the configuration shown. Ollama offers OpenAI-compatible endpoints under /v1/, and the SDK finds them when its base URL points to the proxy with that path. The SDK, however, sends the API key in the header Authorization: Bearer …, while auth_basic expects the Basic scheme with user name and password in the same place. The proxy therefore answers with 401.
The configuration only implements Basic Auth. For Bearer tokens, auth_basic can be replaced by a check of its own: a map in the http block that compares $http_authorization with the valid tokens, and a return 401 in the server block for every request without a match. Each program can then get a token of its own that can be revoked individually.
Why does the curl command use the -k option, and can it stay in production?
The -k option switches off certificate verification so that the test also works with a self-signed certificate. It does not belong in production: without verification, TLS offers no protection against a party posing as the proxy, and Basic Auth credentials are only Base64-encoded, so anyone who intercepts them can read them. Instead, the certificate or the internal certificate authority is added to the clients’ trusted certificates.
Sources
Related articles