English
 Deutsch
 Polski
robots.txt for Search, Training and Assistant Crawlers: What Each Block Prevents

Contents
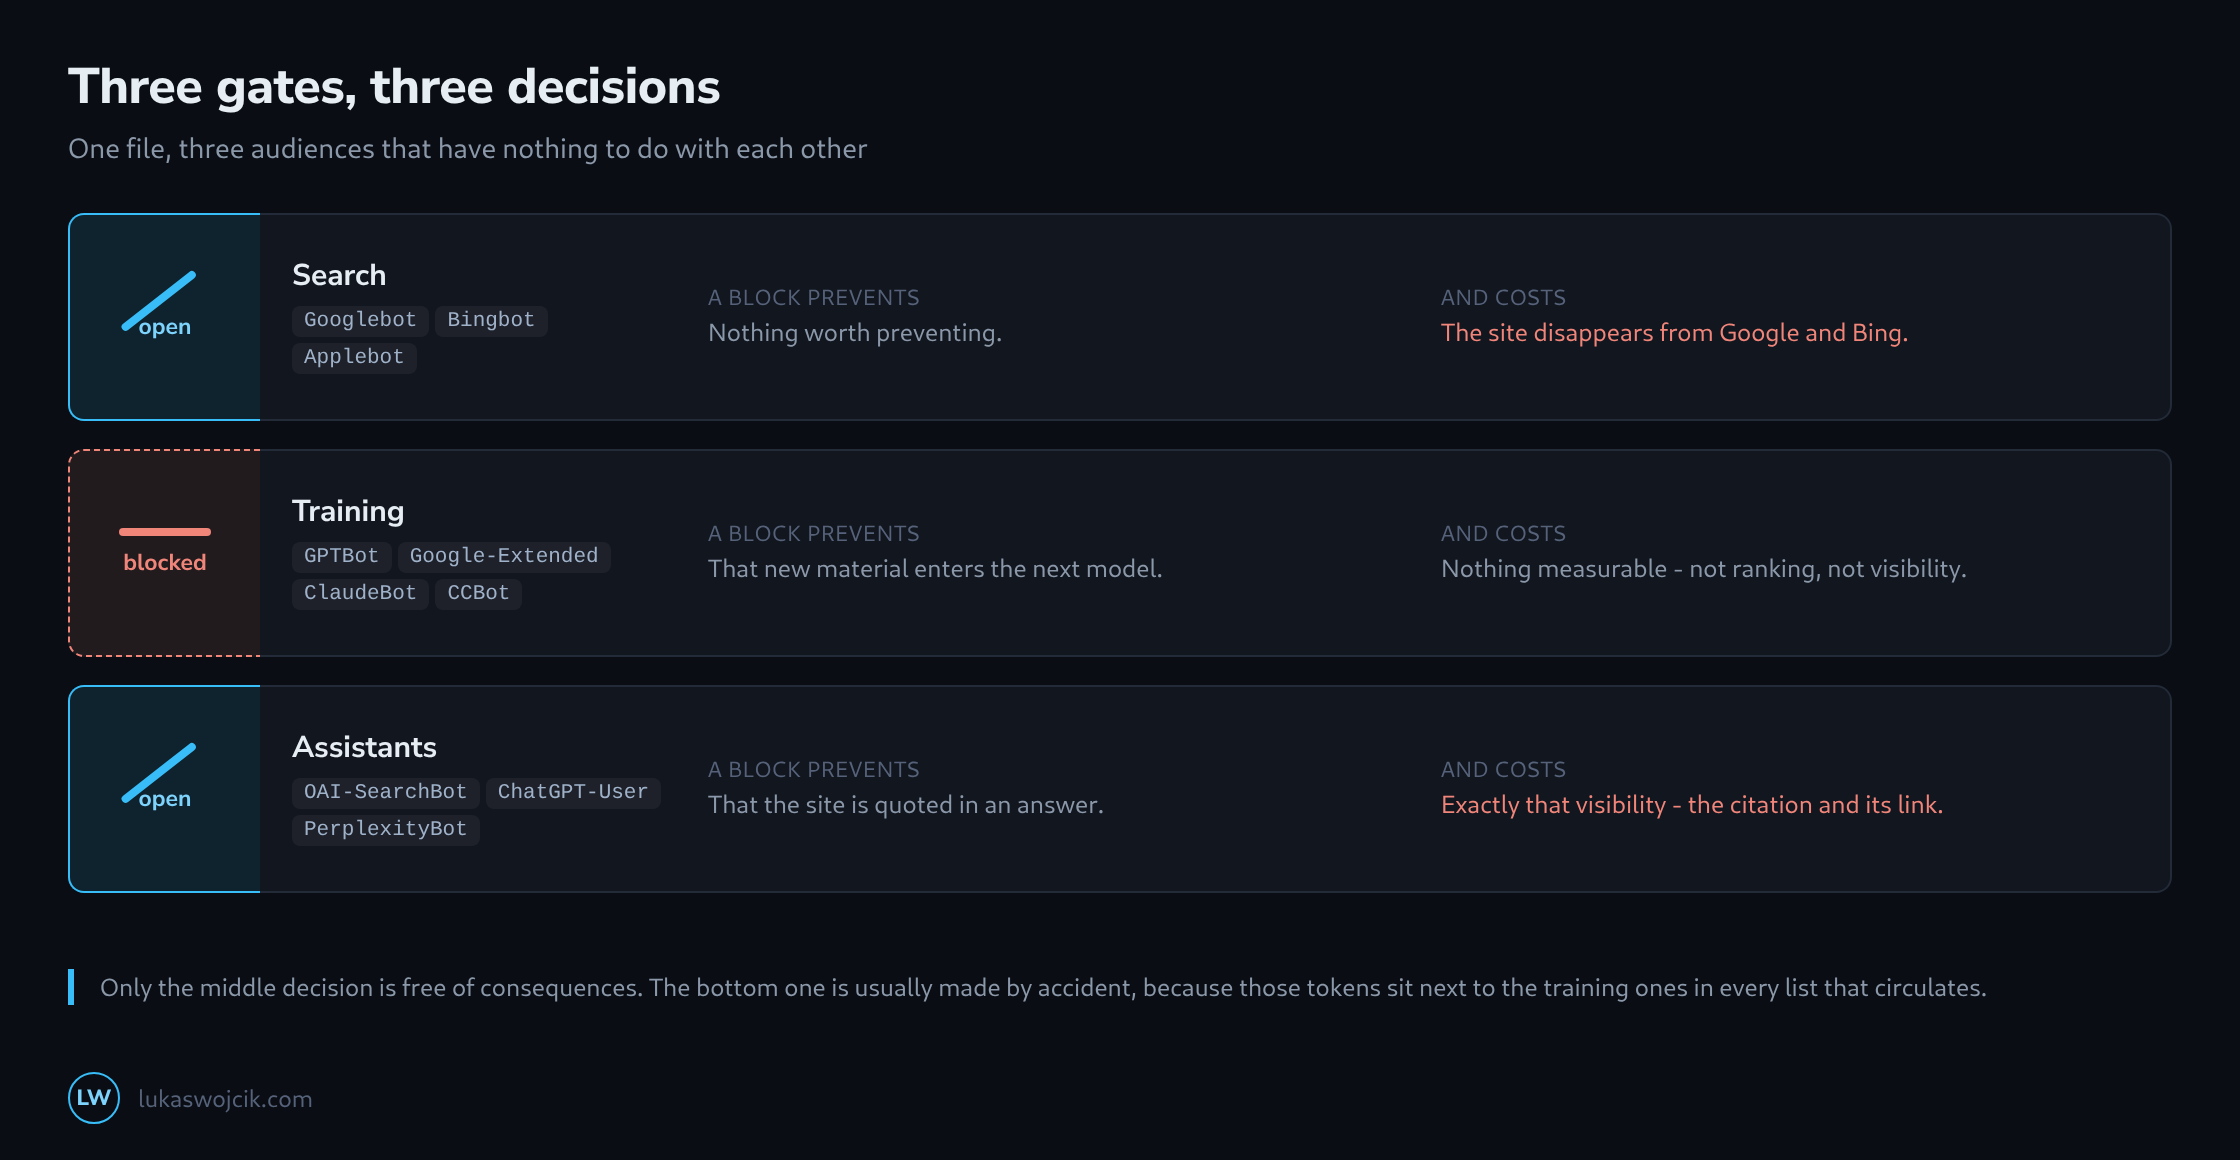
One file, three audiences that have nothing to do with each other. A search crawler fetches a page so it can be found; a training crawler fetches it so a model can be built from it; an assistant fetches it because someone asked a question a minute ago. The three are told apart only by the name they announce themselves with, and blocking one says nothing about the others.
Which is why the usual instruction – block the AI crawlers – is not a decision but three decisions, and two of them cost something that is rarely stated when the line is added.
Three Kinds That Do Different Work
Search crawlers – Googlebot, Bingbot and the rest – build the index that ordinary results come from. Blocking them removes the site from search within weeks, which is why nobody does it on purpose and why it happens by accident: a staging Disallow: / that survives the move to production.
Training crawlers – GPTBot, Google-Extended, ClaudeBot, CCBot and others – collect material that models are built from. They fetch once and read everything; nothing they take comes back as a visit.
Assistant crawlers – OAI-SearchBot, ChatGPT-User, PerplexityBot – fetch a page because a question is being answered right now. What they take often comes back: as a citation, as a link, as the sentence someone reads instead of the search result.
What Each Block Prevents and Costs
| Blocking | Prevents | Costs |
|---|---|---|
| Search | Nothing worth preventing. | The site disappears from Google and Bing. |
| Training | That new material enters the next model. | Nothing measurable – not ranking, not visibility. |
| Assistants | That the site is quoted in an answer. | Exactly that visibility – the citation and the link that comes with it. |
The middle row is the one that can be decided on principle without paying for it. The bottom row is the one that gets decided by accident, because the crawler names sit next to the training ones in every list that circulates.
Google-Extended Is Not Googlebot
The distinction that causes the most hesitation: Google-Extended governs whether content is used for training Gemini and the Vertex models and for grounding in Gemini Apps and in Grounding with Google Search on Vertex AI. It has no effect on crawling for Search, on indexing, or on ranking. Blocking it changes nothing about how a page performs in Google, and that is not a claim requiring trust – it is what the token exists for.
The same separation runs through the other providers. GPTBot is training; OAI-SearchBot feeds the search index behind the assistant; ChatGPT-User is the fetch that happens when a user asks. Blocking all three because the names look similar is the most common way a site quietly leaves the answers it wanted to be in.
Nothing Works Backwards
A block applies from the moment it is read. Whatever has already been fetched sits in corpora that were built from it, and those do not consult robots.txt again. A site that has been online for years and adds the lines today has decided about future crawls, not past ones.
That is worth saying plainly because the decision is often framed as removal. It is not removal; it is a fence around what has not been taken yet.
llms.txt: a Map, Not a Rule
The file at /llms.txt is the opposite of robots.txt in intent: it does not forbid, it points. A short markdown document naming what the site is and which pages carry the substance – a table of contents for something that reads without navigation.
Two things to be clear about. It is a proposal rather than a standard, and no crawler is obliged to look for it. And it does not restrict anything: a page listed there is not thereby permitted, and a page missing from it is not thereby protected. It costs ten minutes to write and is worth exactly what a good table of contents is worth – nothing at all if the pages behind it are thin.
What robots.txt Cannot Do
It is a request, not a lock. Every crawler decides for itself whether to obey, and the ones that do are the ones that publish a name to be blocked by. Anything that ignores the file is not affected by anything in it.
And it does not keep a page out of search results. A blocked page that others link to can still appear, without a description, because the crawler was not allowed to read what it says. Keeping something out of the index takes a noindex – which requires the crawler to be allowed in to read it – and keeping something private takes authentication. robots.txt sits below both, and works well for exactly what it is: traffic direction for the crawlers that agreed to be directed.
Three Details Behind the Names
Google-Extended cannot be blocked at the server
Google-Extended has no user agent string of its own. Google’s crawler documentation states that crawling is done with the existing Google user agent strings and that the token is used in robots.txt purely in a control capacity. No request ever arrives under that name, so a firewall or server rule matching it catches nothing, and a rule against the agent that actually fetches, Googlebot, takes the site out of Search. For Google’s training and grounding question, the robots.txt entry is the only lever.
CCBot feeds a public archive
CCBot is the crawler of Common Crawl. It identifies itself as CCBot/2.0 and follows robots.txt. The crawl data is stored on Amazon S3 and published as an open dataset with as few restrictions as possible. What CCBot fetches therefore does not stay with a single model provider; it is available to anyone who downloads the archive. Blocking the training crawlers of individual providers while CCBot stays open leaves that indirect route in place.
A name listed twice is merged, not raffled
Files that grow over years sometimes name the same crawler in two groups. RFC 9309 settles that case: crawlers match the name case-insensitively, and if more than one group matches, their rules are combined into a single group. Within that merged group the longest matching rule decides, as in any other group. Two groups for GPTBot, one with Disallow: / and the other with Allow: /blog/, therefore leave /blog/ open, which may not be what was intended when the blocking group was added. Searching the file for each crawler name shows such duplicates in seconds.
Questions and answers
Does a rule under User-agent: * also apply to a crawler that has its own group in the file?
No, and this is exactly where adding the AI crawler names tends to go wrong. Under RFC 9309 a crawler follows the group that carries its name, and only if there is no such group does it follow the group under User-agent: *. The two are not merged. A separate group for OAI-SearchBot with Allow: /, meant to admit the assistants explicitly, therefore also lifts, for that crawler, every block listed under *, such as the one for the admin area.
Rules meant for everyone have to be repeated in every named group. Within a group the longest matching rule then decides, and on a tie the RFC says Allow should win. That makes it possible to block a site except for one directory without listing every path individually.
How can a fetch be confirmed as really coming from Googlebot or ChatGPT-User rather than merely using the name?
Not from the name, because any sender can put whatever it likes in the user agent. What holds up is the origin of the request, and there are two ways to establish it:
- Reverse and forward lookup. The hostname for the IP address is looked up; for Google’s crawlers it ends in googlebot.com, google.com or googleusercontent.com. That hostname then has to resolve back to the same address, otherwise the entry is forged. Google describes this procedure itself.
- Published address ranges. Several providers, Google and OpenAI among them, publish the IP ranges of their crawlers as machine-readable lists, split by crawler type. Matching against them can be automated and needs no DNS query per request.
For robots.txt this makes no difference: a fetch posing as Googlebot and ignoring the file is not affected by anything in it anyway. The check matters once a block is to be enforced on the server, in a firewall for example. It then belongs in front of every rule that decides by name, so that an exception for genuine search crawlers is not open to anyone who uses that name.
What happens when robots.txt itself cannot be reached or returns an error?
That depends on the status code, and the two cases work in opposite directions. Under RFC 9309 a response in the 400 to 499 range counts as a missing file: the crawler may fetch everything. A server error in the 500 to 599 range, or a network failure, counts as a complete block instead; only if that state lasts a long time (the RFC gives 30 days as an example) may the crawler fall back on a cached copy or treat the file as missing.
Two traps in the rest of the setup follow from this. A rule in the server configuration that accidentally catches robots.txt as well and answers it with 403, 404 or 410 lifts every block in the file. An overloaded server that answers robots.txt with 503, on the other hand, keeps the search crawlers away too. And every change only takes effect once the crawler fetches the file again; the RFC recommends not using a cached copy for more than 24 hours.
Does blocking Google-Extended also affect AI Overviews in Google Search?
No. AI Overviews are part of Search and draw on what Googlebot has crawled, which Google-Extended does not affect. How much of a page appears there can only be limited through snippet controls such as nosnippet or max-snippet, or prevented altogether with noindex, and both then apply to the ordinary search result as well.
Related articles