English
 Deutsch
 Polski
Querying Microsoft Clarity via MCP: Ten Requests a Day, Three Days of History

Contents
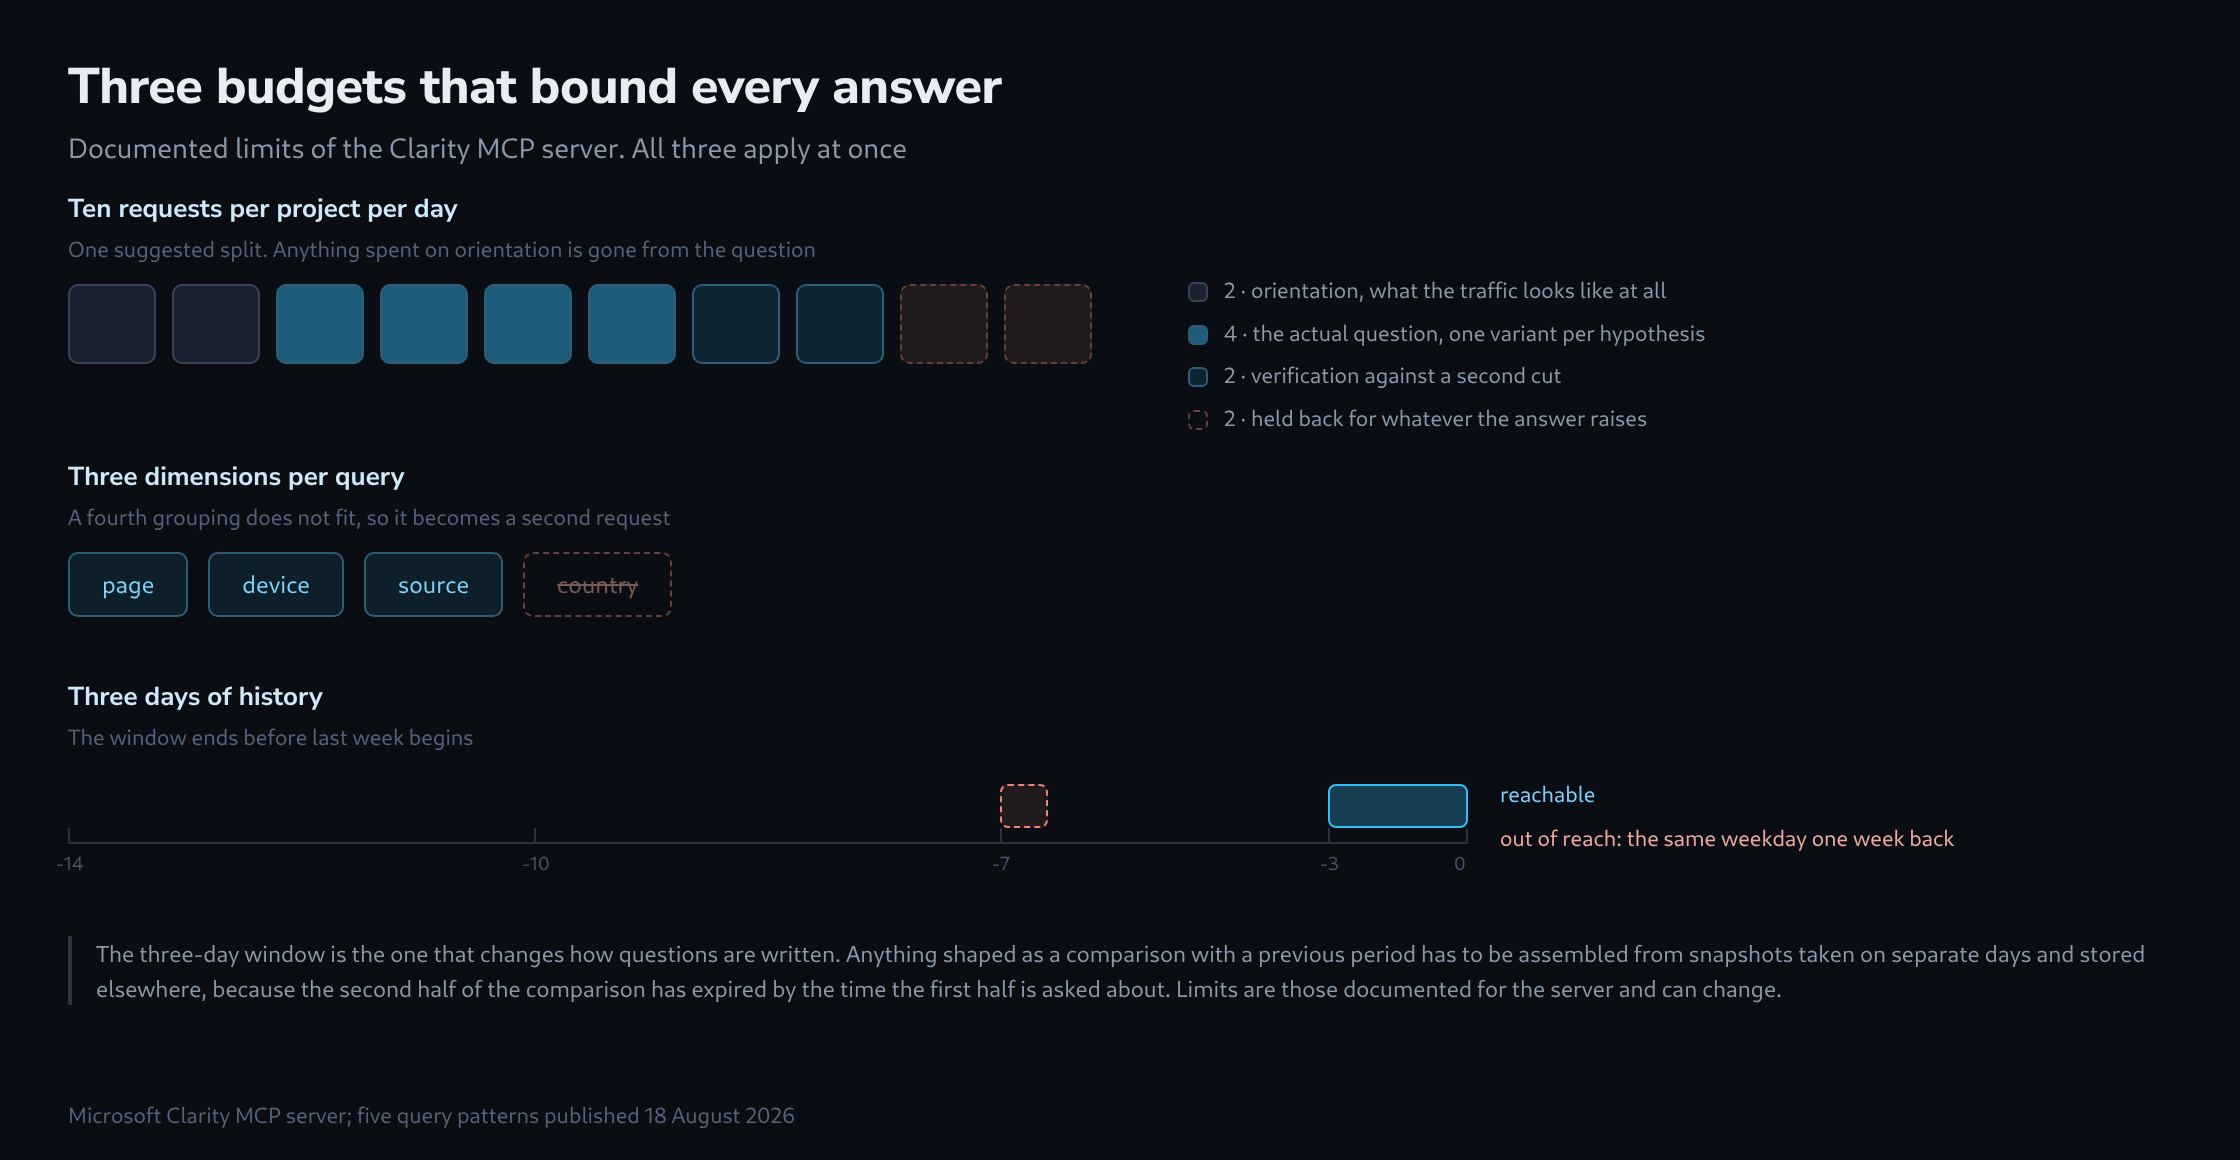
Microsoft published five example query patterns for the Clarity MCP server on 18 August 2026. The patterns themselves are unremarkable, which is fine, because the useful part of the announcement is the constraint they operate under. Three limits apply simultaneously, and together they change what kind of question is worth asking at all.
Ten requests per project per day. Three dimensions per query. Three days of history. Any one of those is a nuisance; the combination is a design problem.
What the three-day window rules out
Almost every routine analytics question is a comparison, and almost every comparison reaches back further than three days. Week over week is the standard unit precisely because it cancels the weekday effect, and the point it needs – the same weekday, seven days ago – has expired before the window opens.
A better-worded prompt cannot retrieve data that is no longer available. Instead, use the server to collect snapshots rather than a time series: save today’s query result, run the same query next week and compare the results outside the tool.
Spending ten requests
A budget this small rewards deciding the split in advance, because the failure mode is spending six requests discovering what the traffic looks like and then having four left for the thing that mattered.
2   orientation      volume and shape, one for sessions,
                     one for the pages carrying them

4   the question     one request per hypothesis, phrased so
                     that the answer eliminates a hypothesis
                     rather than describing the data again

2   verification     the same finding cut a second way
                     a finding that survives one recut is
                     usually real

2   reserve          for whatever the first eight raised
                     unspent by the end of the day is fine;
                     the quota does not roll over
The one habit worth forming is phrasing requests so that each answer removes a possibility. A question whose answer is a description costs the same as a question whose answer is a decision, and only one of them is affordable ten times a day.
The three-dimension cap
Three groupings sound generous until a real question needs page, device, source and country at once. What the cap forces is a choice about which dimension is the subject and which are context, and that choice is usually clarifying rather than limiting.
The workaround is to fix one dimension as a filter instead of a grouping. Asking for page by device by source within one country spends the country as a constraint rather than a column, which stays inside the cap and answers the same question. It also produces a smaller answer, which matters when the answer is being read by a model with its own context to manage. There is a second reason as well: the Data Export API behind the server limits every response to 1,000 rows and offers no pagination, so a finer breakdown does not continue on a second page but ends at row 1,000.
Where this sits next to the rest of Clarity
The MCP server is not the whole product and was never meant to replace the interface. Clarity’s own reports carry the long history, the session recordings and the heatmaps; the server exists so that a question can be asked in a sentence instead of assembled by hand.
Which makes the sensible division of labour fairly clear. Exploratory questions with a short reach go through the server, where a sentence is cheaper than a click path. Anything historical, anything periodic and anything that has to be reproduced on a schedule belongs in the interface or in an export, because the constraints that make the server pleasant to talk to are the same ones that make it unsuitable for a report.
One caveat worth carrying: these limits are the documented ones, and documented limits move. A pipeline built to sit exactly at ten requests will break quietly on the day the number changes in either direction.
Questions and answers
Does one question in the chat count as one request against the daily quota?
Not necessarily. The quota applies to the queries that reach the Clarity project, and a model can issue several of them for a single question, for instance when it follows up or repeats a query with different dimensions. Planning the budget is easier when the model is instructed to ask for confirmation before each further query.
What belongs in a snapshot so that it is still comparable a week later?
Everything that determines the query, not just its result. Two cuts are only comparable if they were produced the same way. The following should therefore be stored alongside it:
- the exact wording of the question or, better, the query parameters the model turned it into: dimensions, filters and look-back;
- the time of retrieval, including the time zone, because the window moves with it;
- the raw response, not just the model’s summary, because a summary cannot be recut afterwards.
The retrieval time deserves the most care. As long as it is not established whether the look-back depends on calendar days or on the clock time of the request, the same weekday at the same time is the safe choice; that way the weekday effect which the week-over-week comparison is meant to cancel drops out.
This suits the budget: one fixed cut per week costs one request on the day it is taken, and the remaining nine stay available for that day’s work.
What does the quota mean when several people query the same project?
That they share the ten requests. The limit applies per project and day, not per person or per access. A scheduled retrieval in the morning, a colleague testing a hypothesis and a second tool querying the same project all draw on the same budget, and whoever comes after the tenth request gets nothing.
The split into orientation, question, verification and reserve thus becomes an arrangement between people: who uses which requests, and who may draw on the reserve. Scheduled retrievals belong at the start of the day, so that a failure is still noticed while requests are left.
Related articles