English
 Deutsch
 Polski
Conversational Analytics in Looker: Token Billing From 1 October 2026

Contents
Conversational Analytics in Looker is free until 30 September 2026. From 1 October the meter starts: three dollars per million input tokens, twenty dollars per million output tokens, charged as overage against a monthly allowance that each user carries.
The interesting number is not either price. It is the ratio between the two allowances, and what that ratio implies about which questions are worth asking in a chat box rather than building as a report.
The allowance is per person, not per pipeline
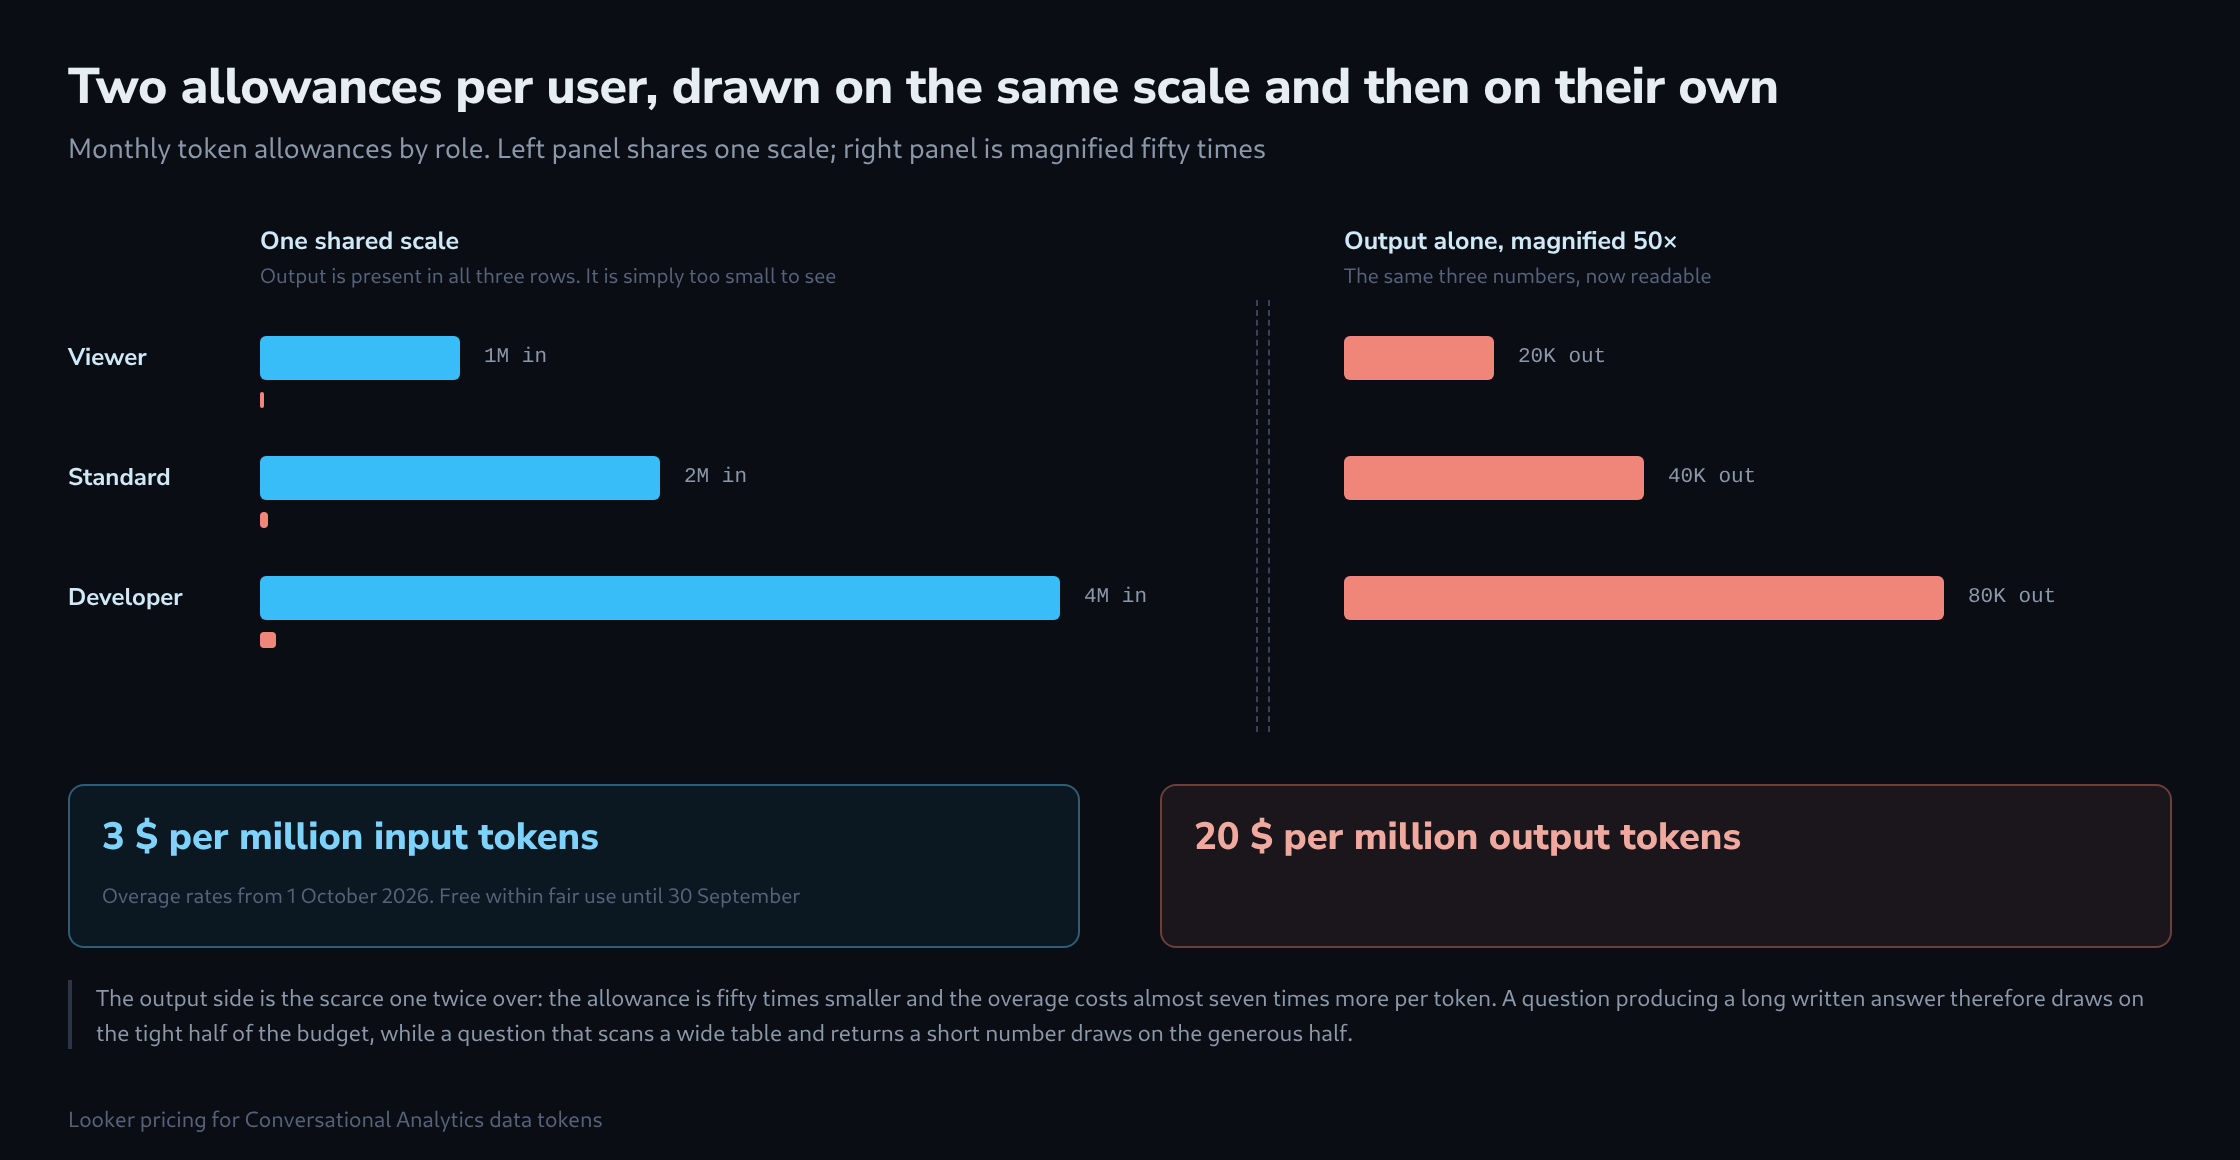
This is the structural difference from every other token bill. An API key has usage; a report user has a role. Here the monthly allowance is attached to the role: one million input and twenty thousand output tokens for a Viewer, two million and forty thousand for Standard, four million and eighty thousand for Developer.
Which means the cost of the feature scales with how many people use it, not with how much data it touches. Twenty analysts asking occasional questions can sit comfortably inside the free allowance. One analyst automating a daily narrative summary for twenty dashboards will not, and no amount of query optimisation changes that, because the expense is in the writing rather than the reading.
Why output is the tight half
allowance ratio     1,000,000 in  :  20,000 out      50 : 1
price ratio         3 $/M in      :  20 $/M out    1 : 6.7

  combined: an output token is scarce fifty times over
  and expensive nearly seven times over

cheap question      scans a wide table, returns a number
                    heavy on input, trivial on output

expensive question  "summarise what changed this month
                    and explain why" - light on input,
                    every word of the answer on output
Other token bills may lead you to focus on how much data goes in. Here the input allowance is more generous and input tokens are cheaper. The tighter limit is the length of the answer.
A rough sense of scale helps. Twenty thousand output tokens is on the order of sixty to eighty substantial answers in a month for a Viewer, assuming a few hundred tokens of prose each. That is fine for someone who asks a question when something looks odd. It is not fine as the interface to a daily routine.
What this changes about how to use it
The division that falls out of the pricing is close to the division that was sensible anyway. Ad hoc questions, asked because a chart looked wrong, are exactly what a conversational interface is for and they fit inside the allowance without anyone thinking about it.
Recurring output belongs in a report. A narrative that gets generated every Monday morning for the same six dashboards is a template with numbers in it, and a template does not need a language model to fill in once its shape is fixed. Paying twenty dollars a million to regenerate the same sentence structure fifty-two times a year is the failure mode worth naming in advance.
An occasional written summary for a stakeholder who will not open Looker themselves calls for judgement. The summary has value and consumes output tokens; whether it is worthwhile depends on the stakeholder’s needs, rather than the price sheet alone.
What to do before October
Two things, neither of them large. First, find out what current usage actually is while it is still free, because after 1 October the same behaviour arrives as a line on a bill and nobody will remember what the baseline was.
Second, look for anything already running on a schedule. Scheduled generation is where a free feature quietly turns into a recurring charge, and the month to find it is the one before the meter starts rather than the one after.
Questions and answers
What does an automated daily summary for twenty dashboards cost per month?
Little enough to be overlooked, and that is the catch. A worked example using the article’s own assumptions: one answer of about 300 tokens of prose per dashboard, twenty dashboards, thirty days. That comes to 180,000 output tokens a month. After the 20,000 in a Viewer’s allowance, 160,000 tokens of overage remain, which at twenty dollars per million is $3.20 a month. Input is not included here; it only starts to count once it exceeds the million in the allowance, and then costs three dollars per additional million.
The amount on its own is therefore not the argument. What matters is the shape of the cost: it grows linearly with every additional dashboard and every additional person who sets up the same routine, it recurs every month, and it pays for work that a fixed template would do without a language model. On top of that, at 6,000 tokens a day the routine uses up the allowance after just over three days. Nothing is then left for the occasional questions the interface is meant for, and each of those goes into overage as well.
Is it worth moving users to a higher role to enlarge their allowance?
Hardly. The step from Viewer to Standard adds one million input and 20,000 output tokens, worth $3.40 a month together at overage prices; the step from Standard to Developer is worth $6.80. A role change cannot save more than that in token costs, and only if the extra allowance is used in full. The role also governs what a person is allowed to do, so assigning it by allowance rather than by task widens permissions to save a few dollars.
How can a question be phrased so that it uses few output tokens?
By asking for a number, a short list or a table rather than an explanation. “What was revenue by region in August?” weighs mainly on the input, “Why was August weak?” mainly on the output; the why question pays off only once the figures have shown where the search should start.
Sources
Related articles