English
 Deutsch
 Polski
Chunk Size and Overlap in a RAG Knowledge Base: Effects on Embedding Count, Token Budget and Re-Indexing

Contents
A knowledge base for an AI assistant begins by cutting long documents into short chunks. Two numbers decide how that happens: how long a chunk should be, and how far two consecutive chunks overlap. Both are entered in a minute, apply to the whole corpus, and can only be changed afterwards by running everything through again from the start.
And both are paid twice: once when the knowledge base is built, and then again at every single question. Which is why they are worth calculating rather than guessing.
The unit of measurement is the token – roughly a word fragment; a hundred tokens is about seventy-five words of English prose. Every finished chunk is translated into a long sequence of numbers that captures its meaning. That sequence is called an embedding, and the search later runs through those numbers rather than through the text.
Why the Overlap Costs Money
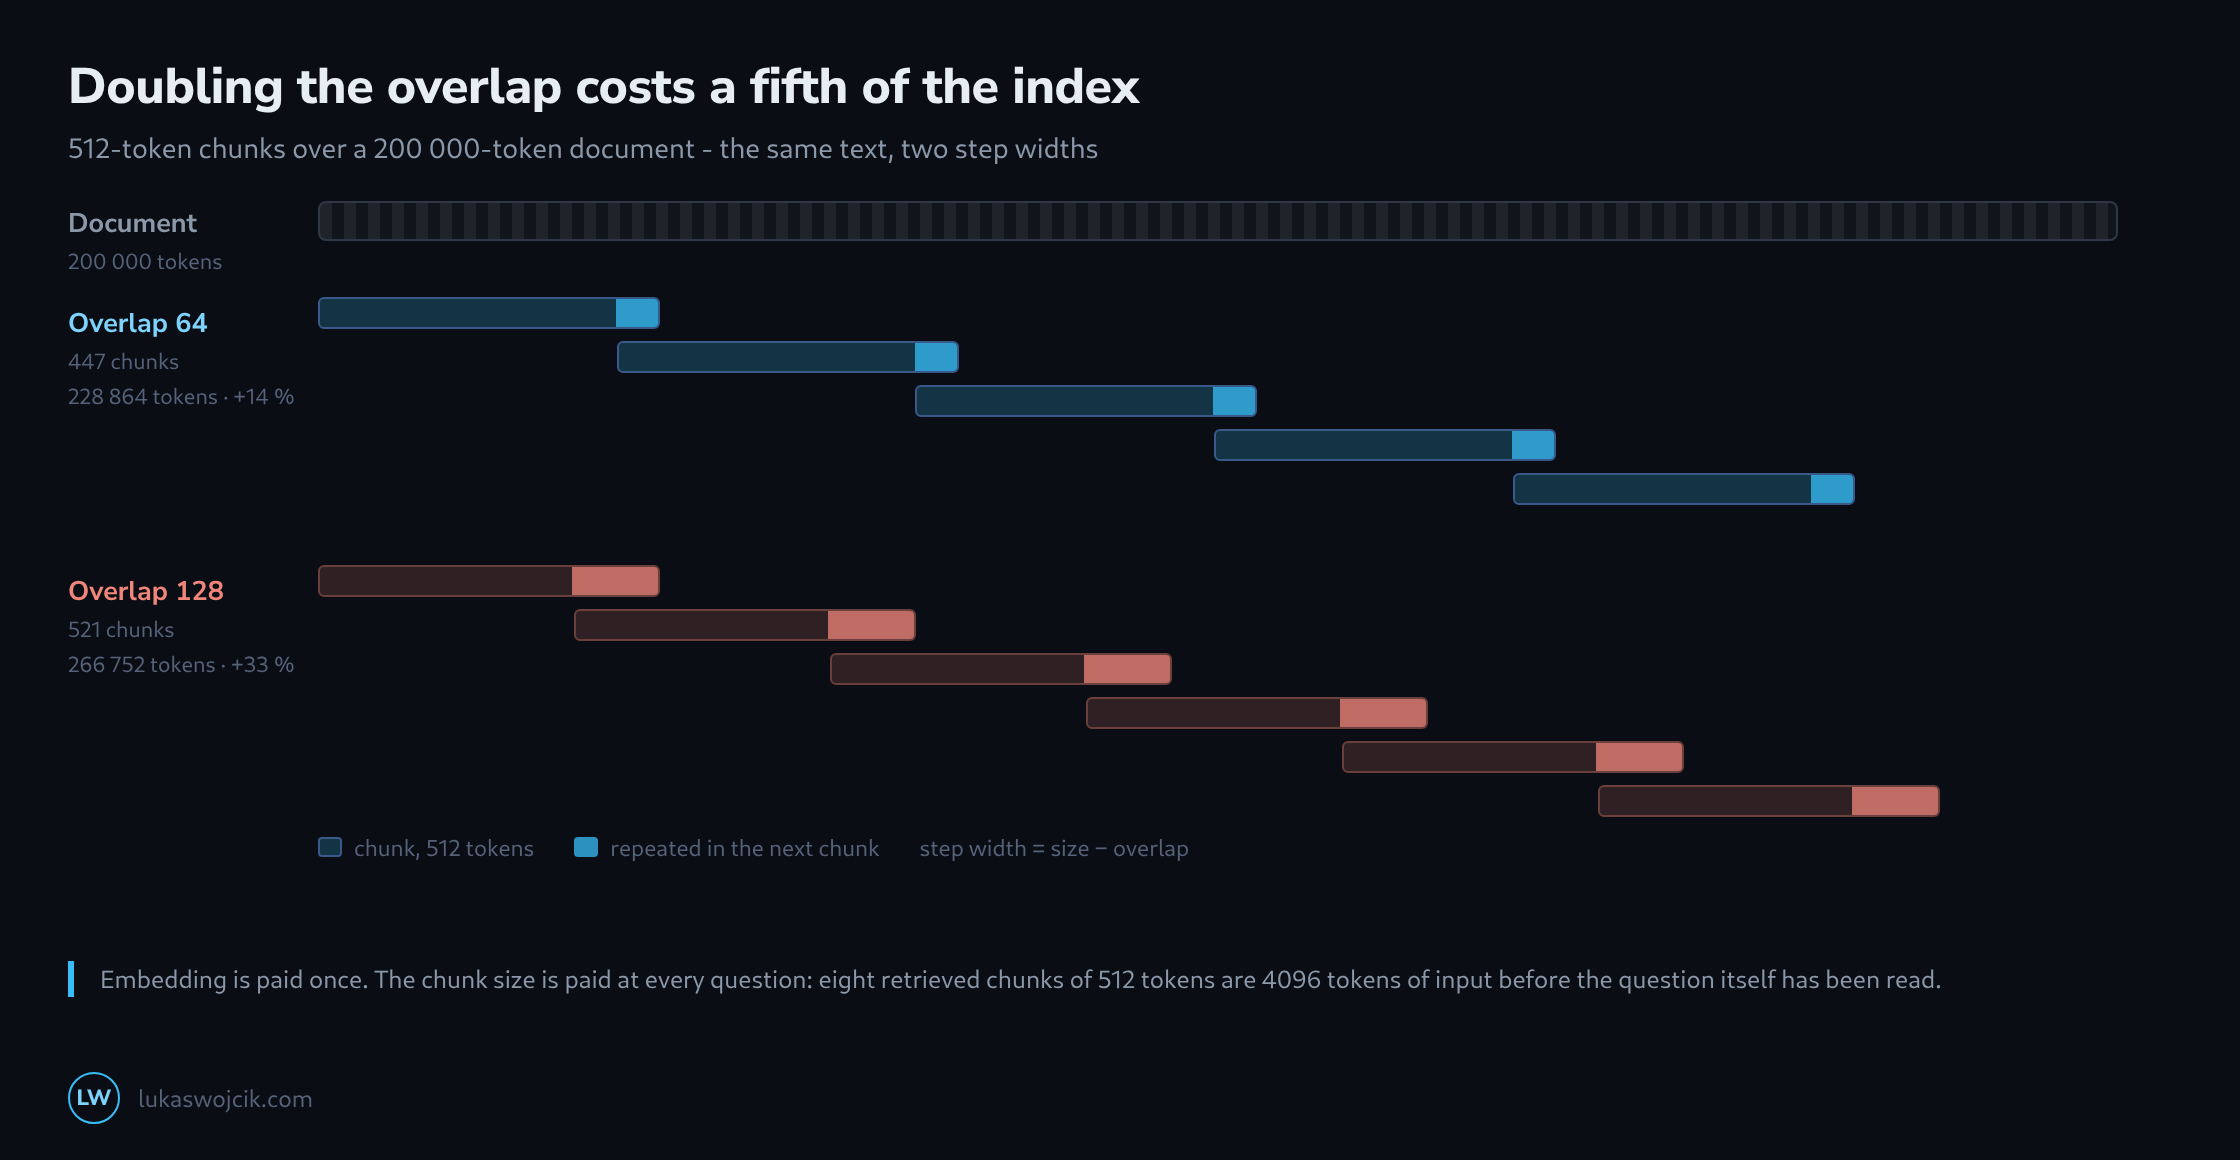
Chunks do not advance by their full length, only by the part that does not overlap. With a chunk size of 512 tokens and an overlap of 64, each chunk advances by 448. That means more chunks for the same document – and because every chunk is stored at full length, the overlapping part ends up in storage twice.
The table shows what that means for a document of 200,000 tokens at a chunk size of 512.
| Overlap | Chunk advances by | Number of chunks | Stored in total | Overhead |
|---|---|---|---|---|
| 64 tokens (12 %) | 448 | 447 | 228,864 | +14 % |
| 128 tokens (25 %) | 384 | 521 | 266,752 | +33 % |
| 256 tokens (50 %) | 256 | 781 | 399,872 | +100 % |
The last row is the one worth remembering: an overlap of half the chunk size stores every token twice. The overhead does not grow evenly with the overlap but shoots up as soon as the advance gets narrow. That is why the useful range sits between ten and twenty per cent, and why anything above a third needs a reason.
What the Overlap Is Actually For
A fixed split cuts wherever the counter runs out, which is regularly in the middle of the sentence that contains the answer. The overlap exists so that the sentence appears whole in at least one chunk – and that is its entire job.
Which means the overlap only has to be as large as the passage that must not be torn apart. For prose, two or three sentences is generous, and two or three sentences is about sixty to a hundred tokens. Numbers larger than that are usually chosen out of caution and paid for in storage without buying anything: a sentence that already fits whole into one chunk does not fit more whole because it also appears in the next.
Splitting at Structure Beats Splitting at a Number
The better fix for the same problem is not to cut mid-sentence in the first place. Splitting at headings, then at paragraphs, and only falling back to a token count when a paragraph exceeds the size, removes most of the reason the overlap exists – and it produces chunks whose contents belong together, which is what the embedding is supposed to represent.
The addition that costs almost nothing is to store the heading path with each chunk and prepend it to the text. A chunk that begins with Handbook > Billing > Cancellation retrieves better and reads better when it arrives in the prompt, because it carries the context that the split took away.
Two Sizes, Two Different Failures
| Chunk size | What it does well | How it fails |
|---|---|---|
| 128 – 256 | precise retrieval, the hit is exactly the passage | the passage arrives without the sentence that explains it |
| 400 – 800 | a paragraph with its context, one topic per embedding | barely at all; this is the working range |
| 1024 – 2048 | whole chapters, nothing is ever cut off | the embedding averages several topics and matches nothing sharply |
The failure of large chunks is the one that is hard to see from the outside. An embedding is a single point for the whole text, so a chunk covering three subjects sits somewhere between all three and is close to none of them. Retrieval does not report this; it simply returns something else instead, and the answer is built from a passage that was not quite the right one.
The Cost That Recurs
Embedding a corpus is cheap and happens once. But the chunk size is also the unit in which the retrieved text is measured, the text the assistant is handed at every question – and that is paid for every time. Eight chunks of 512 tokens is 4096 tokens the model reads before it has even seen the question.
That is the number to size against, because it multiplies by the number of questions rather than by the size of the corpus. Halving the chunk size while doubling the number of retrieved chunks keeps the bill identical and the precision higher; halving it without touching the count halves the bill and risks arriving with too little context. Both are decisions, and both sit in the same line.
Changing the Setting Means Rebuilding
The chunk boundaries are baked into the embeddings. A different size produces different texts, different embeddings and different identifiers, so there is no partial migration – the corpus is embedded again, and any identifiers stored elsewhere point at chunks that no longer exist.
Which argues for one habit at the start: keeping the raw documents, the split and the embedding as three separate steps with the intermediate result written to disk. Re-embedding is then a rerun of the last step on a corpus that is already prepared, rather than an afternoon of reassembling how the text got in there in the first place.
Questions and answers
Does the overhead from the table apply to other chunk sizes as well?
Yes, because it depends only on the ratio between overlap and chunk size. The amount stored is roughly the document length times the chunk size divided by the advance; at 512 tokens with 64 tokens of overlap that gives a factor of 512 / 448 ≈ 1.14. A chunk of 1024 tokens with 128 tokens of overlap therefore ends up with the same 14 per cent overhead, while one of 256 tokens with 64 tokens of overlap already reaches 33 per cent.
Does the overlap cost something with every question too, not just in storage?
Yes, as soon as neighbouring chunks are retrieved together, and that happens more often than it sounds. Two neighbours share the overlapping text, so their embeddings sit close together, and a question that matches one often matches the other. If both end up among the retrieved chunks, the shared part appears twice in the prompt and is paid for twice.
The lost space weighs more. With eight retrieved chunks, a pair of neighbours takes two places with partly the same content, and the chunk that would have come ninth drops out. The larger the overlap, the more alike the neighbours and the more often this happens; at half the chunk size, two neighbours share half their text.
Two measures keep it small. Adjacent hits from the same document can be merged into one passage before they go into the prompt, dropping the duplicated part. And the selection can be set up so that only the higher-scoring chunk of each neighbouring pair counts and the freed place goes to the next candidate.
What limit does the embedding model itself set on chunk size?
A hard one: every embedding model accepts only a limited number of tokens, and the last row of the size table comes close to that limit for some common models. What matters is what happens when it is exceeded. Vertex AI, the article’s source, silently truncates overlong input by default rather than returning an error. The rest of the chunk is still stored and delivered, but it does not enter the embedding and cannot be found through that chunk.
Two additions are easy to overlook. The prepended heading path counts too, and a chunk that the splitter counted at 512 with its own tokeniser may be longer in the embedding model’s tokeniser. Working close to the limit therefore calls for some headroom, or for switching truncation off so that an overlong chunk shows up as an error.
Does changing a single document mean re-embedding the whole corpus?
No; only a change to the setting does. For a change in content it is enough to delete that one document’s chunks, split the document again and embed the new chunks. This requires every identifier to include the document the chunk came from; otherwise there is no way to tell which entries have to go.
How much of the result is new depends on how the text is split. With splitting by token count, a sentence inserted near the start shifts every later boundary in the document, and every chunk after it changes. With splitting at headings and paragraphs, the change stays within the chunk where it occurs; the others remain identical character for character.
That can be put to use. Storing a checksum of each chunk’s text makes unchanged chunks recognisable, so their embedding and their identifier can be kept instead of being produced again, and references stored elsewhere stay valid. With splitting at structure, a change to a document then usually means only a handful of new embeddings.
Sources
Related articles