

 English
 Deutsch
 Polski
The Evolution of Web Tracking: From Log Files to the Server-Side Future
Part 1 of 5 in the series From pixel to server: tracking that holds

Management Summary
Web tracking records how websites are used so that businesses can assess content, services and advertising. It has grown from server request logs to browser activity measurement and data from business systems, such as confirmed orders. The article explains why these methods coexist: each captures a different part of a visit. Understanding their differences helps interpret reports and choose useful data sources. Moving collection to a server does not automatically recover missing activity or remove privacy obligations.
Contents
Web analytics draws on several sources: requests in server logs, events from browsers and business transactions in backend systems, such as orders recorded by a shop server. New techniques have added to earlier methods rather than simply replacing them. Server-side tracking often complements browser measurement; it does not mean a wholesale return to log-file analysis.
Log files: counting requests and interpreting activity
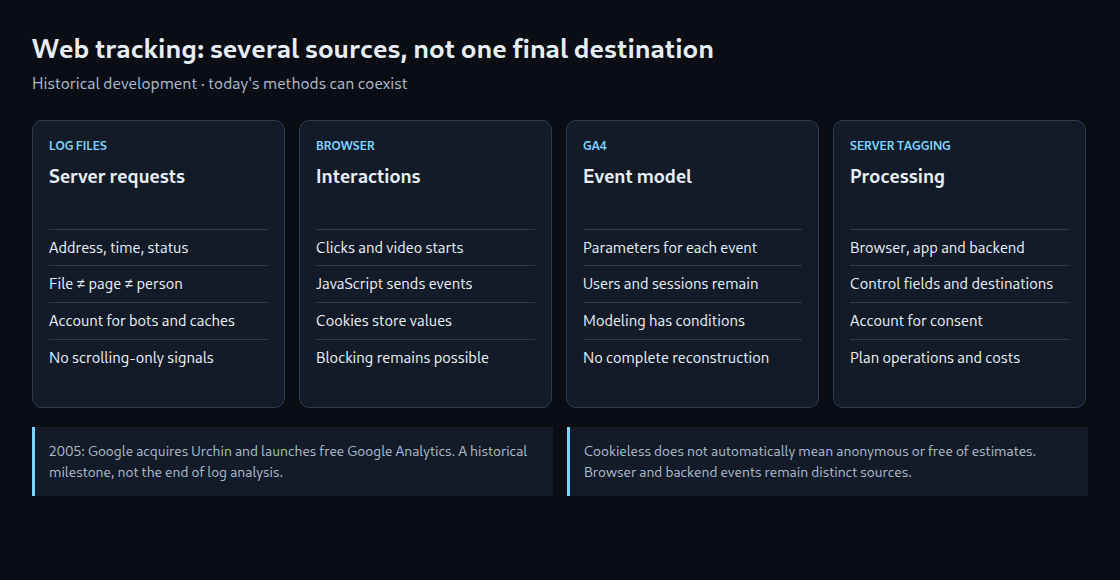
Server logs were an important basis for early web statistics and remain useful for operations and troubleshooting. An access log can contain the time, requested address, response status and IP address. Configuration determines which requests and fields are recorded.
A request is not a visitor or necessarily a page view. One page often loads several files, and bots generate requests too. Browser caches and caches in front of the origin can serve content without contacting the origin server. Scrolling without an additional request does not appear in its access log. Log analysis therefore needs appropriate filters and clearly defined metrics.
Urchin turned web data into reports. Google acquired the company in 2005 and made Google Analytics available free of charge on 14 November 2005. Hosted analytics consequently became easier to access for many websites.
Browser measurement: capturing additional events
JavaScript can detect interactions such as video starts or clicks and send events. Depending on context, a tracking pixel means an image request or, more broadly, a measurement request. Cookies hold values; they are not executable code.
Google Analytics mainly uses first-party cookies, stored under the website’s own domain. A connection to an external analytics server therefore does not necessarily involve a third-party cookie. Universal Analytics reported page views, events, users and sessions. The retired product generation appears here as historical context.
Multiple suppliers and operating models
Google products are only part of this history. Adobe acquired Omniture in 2009. Webtrekk joined Mapp in 2019. Matomo, called Piwik until 2018, offers deployment on an organisation’s own infrastructure among its options. etracker is another web analytics product.
Selection depends on specific features, data flows, contracts, storage locations and operating costs. A European supplier, open-source code or self-hosting alone does not establish compliant configuration. Compliance depends on the current setup and actual processing.
Browser protection and GA4’s event model
Safari’s Intelligent Tracking Prevention and Firefox’s Enhanced Tracking Protection restrict particular tracking techniques. Depending on browser, context and settings, protections can block access or isolate storage. This does not mean a general ban on every cookie.
GA4 organises collection around events and associated parameters. User and session metrics remain part of reporting. Under specific conditions, modeling can statistically supplement missing information: observed patterns are used to estimate values for which no direct measurement is available. It does not promise reconstruction of every lost event; even sufficient data volumes do not guarantee that a property qualifies.
Server-side tagging: an additional processing step
Server-side tagging receives measurement data at a controlled endpoint, an address provided for incoming requests, and processes or distributes events. Sources can include browsers, apps and backend systems. Google Tag Manager recommends a first-party domain for production. Sharing a primary domain is not a general definition of server-to-server communication.
The practical benefit is an inspectable data path: which fields reach each destination, which events are discarded and which consent applies? Correct configuration can reduce browser work. Additional infrastructure also brings costs and requires monitoring, access controls and maintenance.
A server cannot detect scrolling without a signal from the browser. A confirmed order, by contrast, can originate in the order system. Parallel browser and backend delivery requires appropriate deduplication. For example, the same order reported through both paths must count as one purchase rather than two. Server routing does not automatically make blocked, uncollected or impermissible data available.
The share of missing events needs to be assessed for the website concerned. Different sources observe different parts of a visit, so a deviation is not automatically a measurement error. A useful design combines suitable data sources and documents their limits.
Questions and answers
Does cookieless mean no modeling?
No. “Cookieless” initially describes the absence of cookies in a particular collection path. It does not specify other identifiers, session construction or subsequent statistical estimation. Even grouping requests using short-lived request characteristics can be inaccurate. A counted event and an inferred number of people are different claims.
Cookieless collection and modeling can coexist. GA4 reporting distinguishes observed and modeled values. The absence of a persistent identifier limits recognition; whether returning-visitor metrics are possible depends on other permitted signals and the method used.
Does an operator-controlled server replace a privacy assessment?
No. Cookieless techniques can still process personal data or fall within rules governing access to terminal equipment. Purpose, legal basis, possible consent requirements and exceptions depend on the actual method. Hashing, a first-party domain and an operator-controlled server do not independently guarantee anonymity.
Sources
- Apache: Access-Logs
- Google: Urchin acquisition, 2005
- Google Analytics launch, 14 November 2005
- Google Analytics: cookies and identifiers
- Google Analytics: comparing UA and GA4 metrics
- Universal Analytics: retired documentation
- Adobe Annual Report 2009: Omniture
- Mapp: acquisition of Webtrekk, 2019
- Matomo: Piwik renamed in 2018
- etracker Analytics
- WebKit: tracking prevention
- Firefox: Enhanced Tracking Protection
- GA4: behavioral modeling
- Server-side tagging: introduction
- Server-side tagging: custom domain
- Server-side tagging: overview
- EDPB Guidelines 2/2023, version 2.0
From pixel to server: tracking that holds
- The Evolution of Web Tracking: From Log Files to the Server-Side Future
- GA4 & Server-Side GTM: The “Migrate from JavaScript Managed Client ID” Feature Explained
- Server-Side GTM on GCP Cloud Run: Architecture, Auto-Scaling, and Cost Optimization
- GA4 Measurement Protocol: Server-Side CRM Offline Conversion Integration
- Meta Conversions API: Maximizing Event Match Quality (EMQ) and Deduplication
Related articles


