English
 Deutsch
 Polski
Tutorial: Testing Chunk Size and Overlap Against a Retrieval Test Set

Contents
Chunk size gets chosen at the start of a project, usually from an example in a tutorial, and then never touched again. Not because nobody suspects it matters, but because checking it looks like it needs an evaluation framework.
It needs thirty questions, one number, and a loop. And the loop calls no language model at all, which is what makes the whole thing cheap enough to actually run.
The Question a Test Set Has to Answer
Retrieval has exactly one job: put the passage that contains the answer into the shortlist that goes to the model. Whether the model then writes a good answer is a separate question with separate causes, and mixing the two is what makes evaluation expensive.
So the measurement is separable. A test set of questions, each with a known location of the answer in the source material, and a metric that asks how often that location appears in the top k results. Nothing about that requires generation, which means a sweep over eight settings costs the embedding runs and nothing else.
The metric is recall at k. For k equals five: of thirty questions, in how many was the correct passage among the first five hits. Its companion is the mean reciprocal rank, which also rewards being first rather than fifth – useful once recall stops separating the candidates.
Building Thirty Questions Without Writing Thirty Questions
A language model can produce the test set, and this is the one place where it is worth being careful, because the obvious approach produces a set that measures nothing.
Generating a question from a chunk and then testing whether that chunk is retrieved is circular: the question was written from that text, shares its vocabulary, and will find it under almost any setting. The test then says every configuration is excellent.
The way around it is to generate from the document and record where the answer sits, not which chunk it fell into. The chunk assignment happens later, per setting, at evaluation time.
Prompt for the generator, per source document:

  Read the following document. Write eight questions that the document
  answers. For each question, quote the sentence that contains the
  answer, verbatim. Do not write questions that need information from
  outside the document. Vary the wording so that a question does not
  reuse the phrasing of the sentence it comes from.

Result per entry:

  { "frage": "…", "beleg": "verbatim sentence from the document",
    "dokument": "handbuch-2026.md" }
Two manual steps follow and take twenty minutes. Reading through the questions and deleting the ones whose answer is not really in the quoted sentence – the generator produces a few of those. And rewriting the handful that repeat the source sentence almost word for word, because those are the ones that would flatter every setting.
Thirty to fifty entries is the useful range. Below about twenty-five, a single question flipping changes the result by four percentage points and the ranking becomes noise; above fifty, the extra precision no longer changes which setting wins.
Running the Sweep
Each setting means splitting the corpus again, embedding it again, and running the questions through it. The evaluation itself is a substring test: the chunk that contains the recorded sentence is the correct one.
import itertools, json

GROESSEN     = [256, 512, 1024, 2048]
UEBERLAPPUNG = [0.0, 0.2]
K            = 5

def treffer(fragen, index, k):
    n = 0
    for f in fragen:
        gefunden = index.suche(f["frage"], k=k)
        if any(f["beleg"] in c.text for c in gefunden):
            n += 1
    return n / len(fragen)

fragen = json.load(open("testsatz.json"))
for groesse, ueberlappung in itertools.product(GROESSEN, UEBERLAPPUNG):
    stuecke = zerlegen(korpus, groesse, int(groesse * ueberlappung))
    index   = einbetten(stuecke)
    print(f"{groesse:5d}  {ueberlappung:.0%}  "
          f"recall@{K} {treffer(fragen, index, K):.2f}  "
          f"Stuecke {len(stuecke):5d}")
Three details make the run trustworthy. The recorded sentence has to be compared after the same normalisation the splitter applies, otherwise a collapsed line break turns a correct hit into a miss. A sentence that lands exactly on a chunk boundary counts as found if either chunk contains it – which is precisely the case an overlap is supposed to help with. And the embedding model has to stay the same across the whole sweep, because changing it changes everything and the comparison stops meaning anything.
The cost is worth estimating before starting rather than after. Eight settings over a corpus of two million tokens is roughly eighteen million tokens of embedding once the overlap is counted – a few cents to a few euros depending on the model, and small enough that the sweep is cheaper than one afternoon of arguing about it.
Reading the Curve
The result of a run of this kind is nearly always the same shape, and the shape is more informative than the individual numbers.
| Chunk size | No overlap | 20 % overlap | Context tokens per answer at k = 5 |
|---|---|---|---|
| 256 | 0.71 | 0.79 | 1 280 |
| 512 | 0.84 | 0.88 | 2 560 |
| 1024 | 0.89 | 0.90 | 5 120 |
| 2048 | 0.87 | 0.87 | 10 240 |
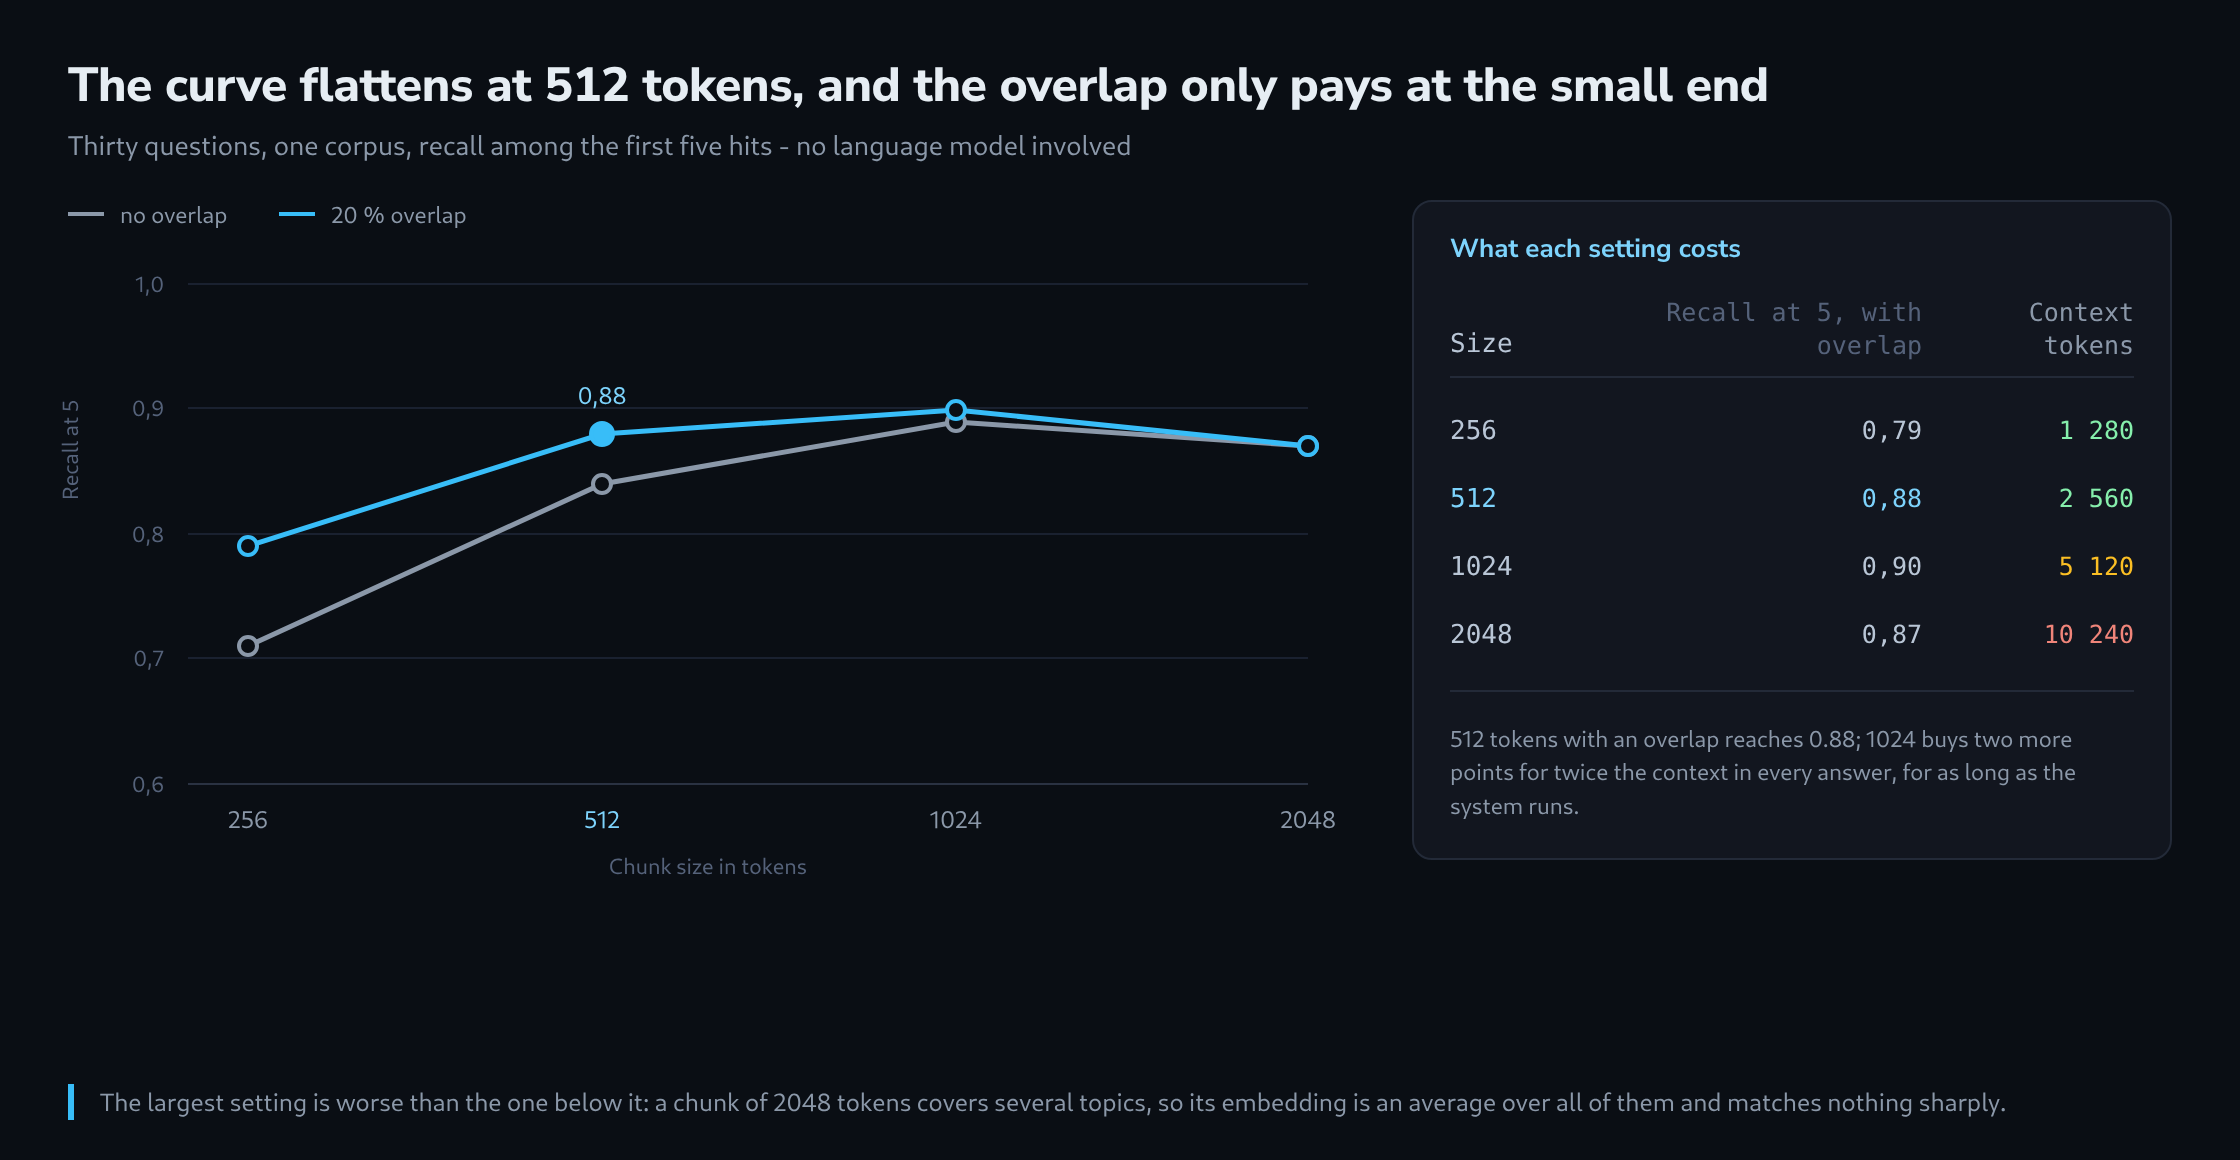
Three readings come out of it. The curve climbs steeply and then flattens, and the point where it flattens is the setting worth taking – here 512, because 1024 buys one or two points for twice the context in every single answer, forever.
The overlap earns its keep at the small end and stops mattering at the large one. That follows from what it is for: it exists so that an answer split across a boundary survives, and the number of boundaries halves each time the chunk size doubles. At 1024 tokens an overlap is mostly a twenty per cent surcharge on the embedding bill.
And the largest setting is worse than the one below it, which surprises people the first time. A chunk of 2048 tokens covers several topics, so its embedding is an average of all of them and matches nothing sharply. Bigger chunks raise the chance that the answer is somewhere in the shortlist and lower the chance that the right chunk ranks first.
One comparison belongs in the same run and usually wins it: splitting at structure rather than at a number. A splitter that breaks at headings and keeps paragraphs whole, with a size limit as a fallback, tends to beat every fixed size on documents that have structure. The sweep shows by how much, which is the argument for spending the afternoon on the splitter instead of on the size.
What the Number Does Not Cover
Recall at k measures one link in the chain, and three things sit outside it.
The first is a reranker. Where one is in use, the retrieval stage fetches a wide shortlist – fifty, a hundred – and the reranker cuts it to five. The number that matters is then recall at fifty, and it looks completely different: it is high almost everywhere, and chunk size stops being the deciding factor. Measuring recall at five in a system that reranks answers a question nobody asked.
The second is answer quality. A retrieved chunk that contains the answer sentence but not the sentence before it can still produce a wrong answer, because the model loses the condition the answer depended on. That is not visible in this metric, and the cheapest way to catch it is to read twenty answers by hand once the setting is chosen.
The third is time. A corpus grows, its vocabulary shifts, and a test set built today gradually stops resembling what is being asked. Rerunning the sweep once a year costs an hour, and the more useful part of that hour is adding the questions that were actually asked in the meantime. A test set drawn from real queries beats a generated one on every measure except how quickly it can be built.
Questions and answers
Is the comparison fair when larger chunks bring more text into the shortlist at the same k?
Only up to a point. At k = 5 the 2048-token setting puts eight times as much text into the shortlist as the 256-token one, and more text contains the recorded sentence more often for that reason alone. It is no accident that the table places recall and context tokens side by side, and the choice of 512 rests on exactly that trade-off. A second sweep separates the two cleanly.
It fixes the context budget instead of k. At 10,240 tokens, the figure for the largest setting, k follows from 10240 // groesse: 40 chunks of 256, 20 of 512, 10 of 1024 and 5 of 2048. In the code it is enough to compute K per size and pass it to treffer(). Every setting then presents the same amount of text, and recall only measures how well retrieval fills that space.
Which of the two comparisons applies depends on the setup behind it. If production passes a fixed number of chunks, the fixed-k sweep is the right one. If the prompt is filled up to a token budget, the fixed-budget sweep answers the question that is actually being asked.
Does a recorded sentence that a split without overlap spreads across two chunks count as a miss?
Yes, even if both halves are among the top k hits. The substring test looks for the whole sentence in a single chunk and finds it in neither. The no-overlap column therefore contains a share that comes from the measurement itself: small chunks have the most boundaries, and part of the gap between 0.71 and 0.79 at 256 tokens may stem from such cases rather than from weaker retrieval.
How large that share is shows up in a second evaluation that counts a sentence as found when its parts appear together in the top k chunks. Both figures have their place. The strict one is the more cautious, because the two halves arrive in the prompt separately and possibly in the wrong order; the lenient one shows what retrieval actually delivered.
Does the chosen setting still hold when the embedding model changes?
Not without checking, because the curve belongs to the pairing of corpus and model. The test set stays usable, though, since it records the document and the sentence rather than a chunk; a model change requires re-embedding the corpus anyway, and a new sweep then only adds the cost of the other settings.
Sources
Related articles