English
 Deutsch
 Polski
410 Gone on robots.txt: How a 4xx Answer on the Rules File Affects Crawler Behaviour

Management Summary
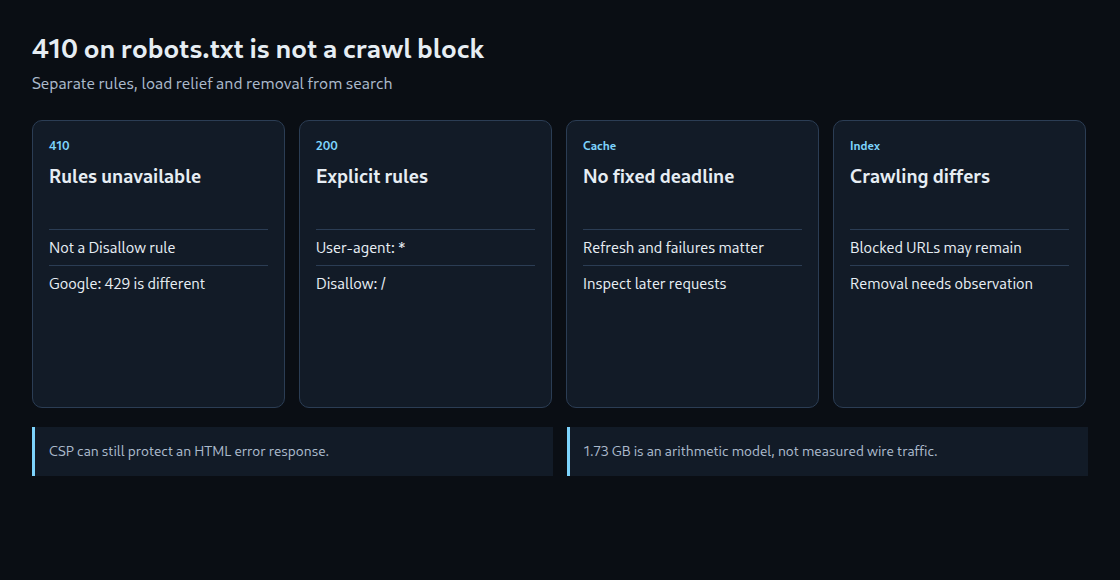
A 410 Gone response tells a visitor or search engine that a page has been removed. The robots.txt file serves a different purpose: it gives cooperating crawlers instructions about access. Returning 410 for that rules file does not tell them to stop visiting the site. This matters during site closure or traffic reduction, because hiding pages from crawlers too early can stop them discovering that content was removed. Reducing server traffic and removing search results therefore require distinct decisions.
Contents
A crawler is a program that automatically retrieves pages, for example for a search engine. A retired hostname can return 410 Gone for removed pages and still receive crawler requests. The response to /robots.txt needs separate attention: a removal status on the rules file is not itself a crawl prohibition.
Page removal and crawling are different decisions
410 indicates that access to the target resource is no longer available and is likely to remain so. 404 does not specify whether the absence is temporary or permanent. Neither code guarantees that requests stop immediately. Google’s current documentation groups ordinary 404 and 410 responses together for removal from its search index over time; a universal faster-removal promise for 410 is not justified.
Why a 410 on robots.txt does not block
RFC 9309 allows crawling when the rules file is unavailable, for example after a 4xx response. That is permission within the exclusion protocol, not authorization to bypass authentication or other access controls. Google’s documented handling treats 4xx responses except 429 as absence of crawl restrictions. The 429 exception matters: it signals overload.
A successful rules response should contain valid UTF-8 plain text. A minimal file for a retired origin is:
User-agent: *
Disallow: /
The file needs an actual successful response; the same text inside a 410 response is not equivalent. Rules apply to the relevant scheme, hostname and port. Existing specific crawler groups or more specific allow rules can change the result, so appending these two lines to a complex file is not a universal block.
A server error is not a permanent replacement
RFC 9309 initially requires complete disallow when the rules file is unreachable through server or network errors, while permitting different handling after a long outage. Google’s documented process starts with a 12-hour crawling pause, then uses the last good copy for up to 30 days. Without a cached copy, its documented later behavior can permit crawling. A deliberately broken rules endpoint is therefore a poor substitute for explicit rules.
The standard’s usual 24-hour cache guidance has an unreachable-file exception. Google also documents variable cache lifetimes. There is no guaranteed next-day deadline, and effects can appear sooner. Successful retrievals, the rule set actually served and later requests provide evidence; elapsed time alone does not.
What the historical incident establishes
The archived article describes a broad 410 rule that also covered robots.txt, plus many parameterized addresses. The figures quoted there are 732,498 responses overall and 698,400 crawler-labelled requests, of which 696,907 addresses were distinct. The original time-bounded request dataset was not available in the reviewed article package, so those values remain historical reported figures rather than independently verified measurements.
The arithmetic gives 1,493 repeated requests, about 0.214% of the crawler-labelled total. A high distinct-address share is consistent with a large URL space, but does not prove an infinite link loop or continued link extraction from 410 bodies. Referrers, generated links, timestamps and verified crawler identity would be needed to establish that causal story. A user-agent label alone is not identity proof.
Response size needs units and protocol context
Using the article’s figures purely as a model, 732,498 × 2,364 bytes equals 1,731,625,272 bytes: about 1.73 GB or 1.61 GiB. At 850 bytes each, the model becomes 622,623,300 bytes, a reduction of about 64.0%. This corrects the earlier 1.65 GB figure.
That multiplication is not measured wire traffic. Header compression in HTTP/2 or HTTP/3, body compression, TLS and transport overhead can change actual transfer size. The claimed per-response measurements need their own capture method and protocol to support a bandwidth claim.
Security headers appropriate to the response
An error status can still carry an HTML document with scripts, links or reflected input. A Content Security Policy (CSP) can restrict which scripts and other resources the browser loads for such a document, so “security headers never belong on refusals” is unsafe advice. A fixed plain-text response may justify a smaller policy, but the decision follows content type and rendering behavior. Other headers serve different purposes and need separate review.
The operational goal
Explicit robots rules can reduce work by cooperating crawlers; they do not stop arbitrary clients or the requests needed to refresh robots.txt. Access controls or rate limits are separate measures. Removing obsolete link generation addresses another possible source of recurring work.
For search removal, a crawler needs access to the 404, 410 or supported noindex response. Blocking first can prevent that observation and leave an already known URL in results. The order depends on whether immediate load relief or index removal has priority; there is no universal wait-until-every-possible-URL-is-gone procedure. Verification covers each affected origin, the rules response, content responses and subsequent traffic.
Sources
Related articles