English
 Deutsch
 Polski
Regular Expressions: The Greedy Dot, Missing Anchors and Nested Repetition

Contents
A regular expression is tested against the case it was written for, it matches, and it goes into production. What it does with the second case is a separate question, and the answer is often that it matches that one too – just not the part anyone intended.
The three mistakes below are the ones that survive review, because none of them fails. They return something, the something looks plausible in a spot check, and the difference shows up as data that is subtly wrong rather than as an error.
The Dot Is Greedy and the Dot Is Not a Character
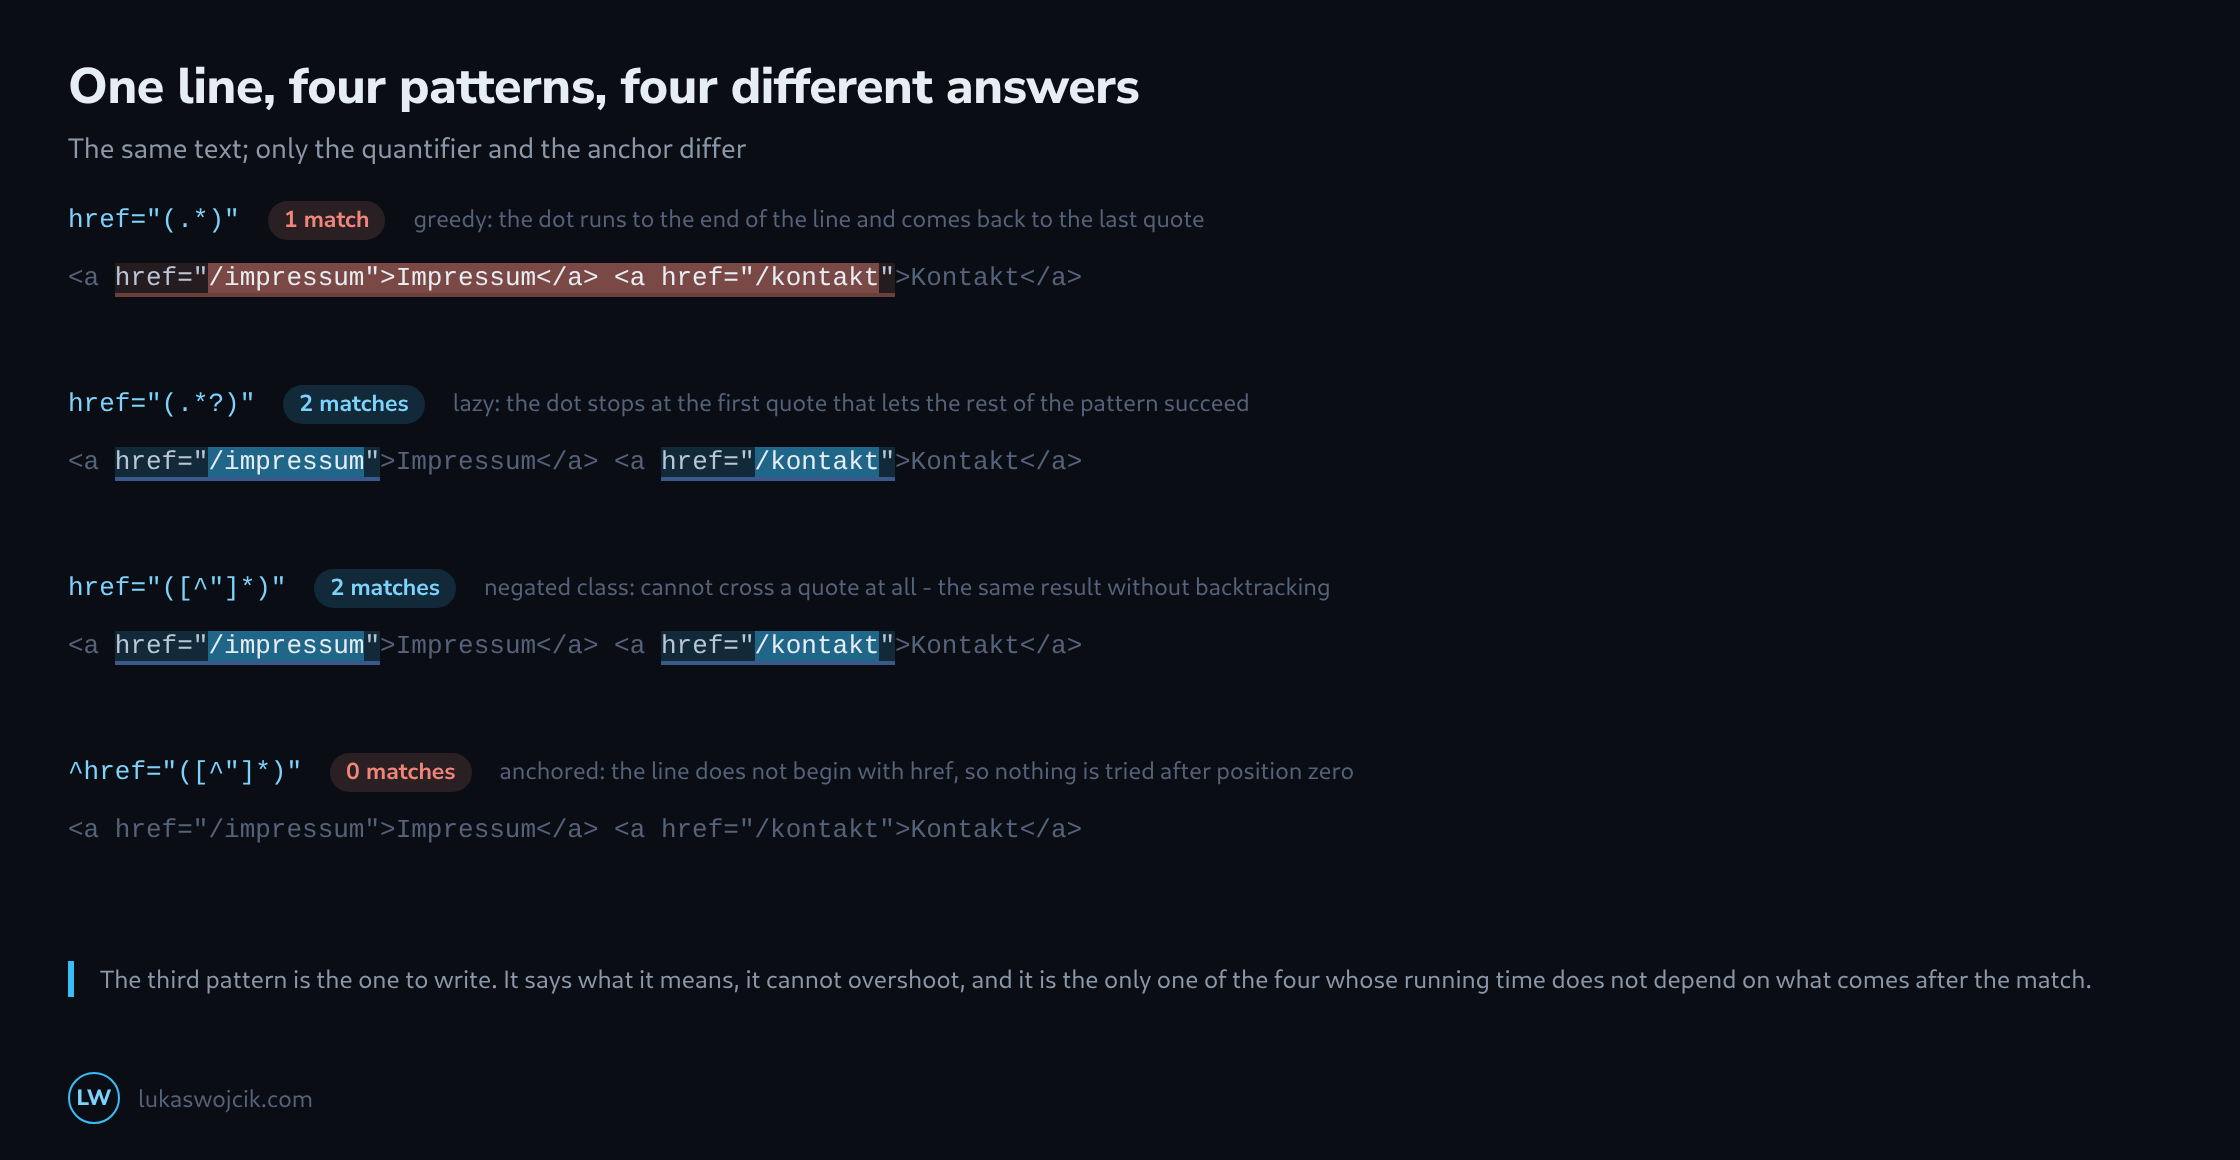
.* takes everything it can and only gives back what it must. In a line with two links, href="(.*)" starts at the first href, runs to the end of the line, then backs up to the last quote it can find – and returns one match containing both links and the markup between them.
Two things fix it. The lazy quantifier .*? stops at the first quote that lets the rest of the pattern succeed. The negated class [^"]* cannot cross a quote at all, which says the same thing without any backtracking – and is the version worth writing, because it states the constraint instead of relying on how the engine unwinds.
A Negated Class Includes the Line Break
The dot does not match a newline unless the s flag is set. A negated character class does – [^&] means anything that is not an ampersand, and a line break is not an ampersand.
text     utm_source=newsletter
         utm_medium=email

^utm_([a-z_]+)=([^&]+)$      with the m flag: 2 matches
^utm_([a-z_]+)=([^&]+)       without it: 1 match spanning both lines
^utm_([a-z_]+)=([^&\s]+)     the fix: whitespace excluded as well
This is the failure that looks like a data problem. A pattern extracting parameters from a multi-line input returns one value that happens to contain everything after it, the value is written to a field, and the field looks like a very long campaign name rather than like a bug.
Anchors Say Where, Not Whether
Without anchors a pattern matches anywhere in the input, which is usually what is wanted for extraction and almost never what is wanted for validation. A check that a field contains only digits with [0-9]+ passes for abc123def, because the pattern was never asked about the rest.
Validation needs ^ and $ on both ends, and it needs to know what those mean in the flavour being used: without the multiline flag they mark the start and end of the whole input, with it every line. Which of the two is correct depends entirely on whether the input is one value or a list of them, and that is a question worth answering explicitly rather than by whichever default the library came with.
Nested Repetition Is a Different Class of Problem
The three mistakes above return the wrong answer. This one returns no answer at all. When a repeated group contains something that is itself repeatable – (a+)+, (\s*\w+)*, (.*,)* – the engine has exponentially many ways to divide the input among the repetitions, and it tries all of them before concluding that there is no match.
| Pattern | Against a non-matching input of length n |
|---|---|
(a+)+$ |
exponential – thirty characters is already seconds |
(\s*\w+)*$ |
the same shape, hidden behind two harmless-looking classes |
^(\w+\s?)+$ |
a common name-validation pattern, and a denial of service |
a+$ |
linear – the outer repetition was the whole problem |
The dangerous property is that these patterns are fast on every input that matches. The blow-up only happens on inputs that fail, which means a validation pattern behaves perfectly for years and then meets one malformed submission and occupies a worker until it is killed.
The rule that avoids it is mechanical: no quantifier directly around a group whose contents are themselves quantified. Where that is unavoidable, a negated class usually expresses the same intent – [^,]+, instead of (.*,) – and removes the ambiguity that the backtracking was exploring.
What to Test Before Trusting a Pattern
Three test inputs answer most of these questions. Start with the case the pattern was written for, to confirm that it matches. Then test a case with two occurrences: this reveals greediness that a single-example test never will. Finally, test a case that must not match. This exposes both anchor problems and nested repetition: the former by matching anyway, the latter by not finishing.
The third is the one that gets skipped, and it is the one that catches both of the problems that cannot be seen by reading the pattern. A test suite for a regular expression is three lines long, and it is the difference between an expression that works and an expression that has not yet been contradicted.
Questions and answers
Does a lazy quantifier help against nested repetition?
No. Whether a quantifier is lazy or greedy only decides the order in which the engine tries the possible splits, not how many there are. On a matching input that can find the match sooner. On a non-matching input the engine has to reject every split before it is allowed to give up, which is why (.*?,)*$ fails just as slowly as (.*,)*$.
What helps is removing the ambiguity, as the article describes: in ([^,]+,)* the class cannot cross a comma, so there is only one way to split any input, and the run time stays linear. Some flavours also offer atomic groups and possessive quantifiers, which never give back what they have consumed; Python has had both since version 3.11.
The third option is an engine without backtracking. RE2, Go’s regexp package and the Rust regex crate work with automata and guarantee a run time that grows linearly with the length of the input; in exchange they do without backreferences and lookarounds. Where input from the network meets patterns whose shape nobody has checked in advance, that is the safest way out.
Are ^ and $ enough in every flavour to validate a single value completely?
Not everywhere. Beyond the multiline flag covered in the article, some differences apply with no flag set at all:
- JavaScript: without the m flag,
^and$mark the start and end of the whole input, exactly as the article describes. - Python and PCRE, and therefore PHP’s preg functions:
$also matches before a single newline at the end of the input, so^[0-9]+$lets123\nthrough. Unambiguous alternatives are\Zinstead of$or a call tore.fullmatch()in Python, and\zor the D modifier in PHP. - Ruby: there
^and$are always line anchors. A multi-line input passes the check as soon as a single line matches, whatever the other lines contain; the whole input is marked by\Aand\z.
The newline that slips through is not harmless. A value that passes the check this way can start a new line in a log entry or a header. Validation therefore calls for the syntax that, in the flavour in use, explicitly means the end of the input.
Is \d the same as [0-9] in every flavour?
Not in every one. In JavaScript it is; in Python 3, by contrast, \d on strings matches any Unicode decimal digit, Arabic-Indic digits for example, unless the re.ASCII flag is set, and .NET behaves the same way. A pattern meant for the digits 0 to 9 only is better written as [0-9], which states the constraint instead of leaving it to the flavour.
Sources
Related articles