English
 Deutsch
 Polski
Freely Available LLMs Compared: Qwen, Gemma, Ministral, Llama and DeepSeek for DE, EN and PL

Management Summary
Qwen, Gemma, Ministral, Llama and DeepSeek offer downloadable language models: AI systems that process text and generate answers. Running these models on owned hardware allows more control over operation. The article compares their suitability for German, English and Polish. The right choice depends on the task, device and permitted use. A free download does not mean unrestricted rights or automatically good results in every language; the value comes from meeting the actual work requirements.
Contents
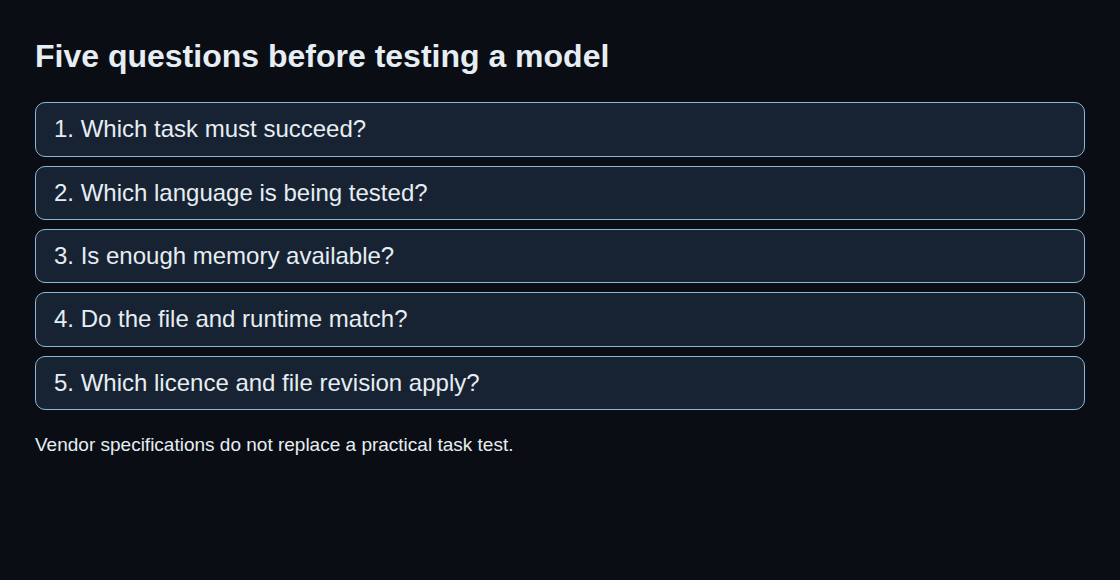
A downloadable language model is not automatically suitable for every local task. It may summarize a German paragraph correctly while omitting important information from the equivalent Polish task. A capable model also helps little if its files do not fit the available memory. This comparison therefore considers task, language, memory, software and usage terms.
The selection gives concrete examples from five model families. These are candidates for a practical test, not a ranking based on original quality measurements. Their sizes differ substantially, and they come from different generations.
Candidate classes
| Candidate | Comparison task | Concrete check |
|---|---|---|
| Qwen3.5-9B | Compact text and image assistant | Does the runtime support this exact architecture? |
| Gemma 4 31B | Larger text and image tasks | Exact model and memory requirements, not just family name |
| Ministral 3 14B Instruct 2512 | Chat and structured text output | Linked files use FP8; check other formats separately |
| Llama 3.3 70B Instruct | Larger text reference for DE/EN | Polish is absent from the supported-language list |
| DeepSeek-R1-Distill | Reasoning tasks at different sizes | Qwen or Llama base, exact size and output limit |
Availability is an incomplete description
Model weights are stored numerical values that determine model behavior. A download provides those files, but does not establish every permitted use. The model description, called a model card, and accompanying licence files need checking. Derived models also require attention to the conditions of their base models.
Qwen3.5-9B, Gemma 4 31B and the linked Ministral 3 14B Instruct entry identify Apache 2.0. Llama 3.3 instead has its own community licence. DeepSeek identifies MIT for R1 and explicitly names the Qwen or Llama base models behind its smaller Distill models. Distillation here means further training a smaller model on outputs from a larger one. Licence assessment therefore concerns the specific files and version, not a brand name as a whole.
DE, EN and PL need separate results
A small test set can contain five tasks: summarize a paragraph, correct a faulty sentence, extract invoice fields as JSON, explain a programming error and answer a question using a supplied document. JSON is a text format for structured data. Expected information and acceptable differences are defined before testing. Each language receives naturally worded tasks with equivalent content.
German, English and Polish receive separate results. Assessment counts incorrect facts, omissions, invalid formats and invented additions. Polish checks can include correctly inflected names and natural, neutral sentence structure. Llama 3.3 lists German and English among eight supported languages, but not Polish. Its model card places other languages outside the intended scope. Additional languages can be addressed through further training (fine-tuning), subject to the licence and appropriate safeguards. A practical test does not replace those usage conditions.
Separate model-class and memory-budget comparisons
One comparison keeps model size approximately equal. Another keeps available memory fixed. Quantisation stores model numbers with less precision to save memory, which can change answers. This allows comparison of a smaller, less compressed model with a larger, more compressed one. Running calculations and longer inputs need memory in addition to the weights.
In a mixture of experts (MoE), only selected subnetworks work in each step. Weights that are inactive at that moment still contribute to storage requirements. Llama 4 Scout contains about 109 billion parameters, although about 17 billion are active per step. It is therefore not equivalent to an ordinary model with 17 billion parameters in total. Moving data into system memory can save graphics memory while slowing responses.
Repeating the test and comparing results
A repeatable test records the exact model identifier, file revision and quantisation. It also records the runtime, meaning the calculation software, the available context length and the chat template that arranges roles and messages. Sampling settings control randomness during text generation. Models with longer reasoning phases additionally need recorded output limits, total elapsed time and usable results. Otherwise a short incorrect response may appear cheaper than a longer correct one. Image tasks are tested separately.
The linked memory estimator provides an initial estimate. A small practical test with verifiable answers follows. The result is a selection for a particular task and language, not a universal winner. Without original measurements, this article cannot identify the best model for Polish or a specific computer.
Memory planning for model selection: LLM VRAM estimator.
Related tools
Questions and answers
Does free availability automatically mean unrestricted use?
Download access and usage terms are separate properties. The licence and conditions of the specific model or derivative determine permitted use.
Is the model with the most parameters automatically best for Polish?
No. Polish task results matter, not just parameter counts. File compression, chat templates and output limits are checked too. The model’s documented language boundaries still apply.
Sources
- Qwen: Qwen3.5-9B, official model card
- Google DeepMind: Gemma 4
- Google: Gemma 4 31B, official model card
- Mistral: Ministral 3 14B Instruct, official model card
- Meta: Llama 3.3 70B Instruct, official model card
- Meta: Llama 4 Scout, official model card
- DeepSeek: R1 and Distill models
Sources checked: 26 October 2026. No original model benchmarks.
Related articles