English
 Deutsch
 Polski
GA4 Thresholding: Distinguishing Privacy Limits, Sampling and Missing Rows

Management Summary
A missing row in Google Analytics does not always mean a visit was never recorded. Reports can hide small groups for privacy, estimate totals from part of the data or combine less common results. These mechanisms answer different problems and have different effects on the figures. The article explains how to recognise the distinction before changing marketing or measurement. In particular, an estimate already expanded from a sample must not be multiplied again as though it were a raw count.
Contents
A missing row in a GA4 report can have several causes. A privacy threshold, a sampled calculation, an (other) row and a truncated date range describe different limitations. The useful question is which mechanism applies to the specific response, before changing collection or campaign settings.
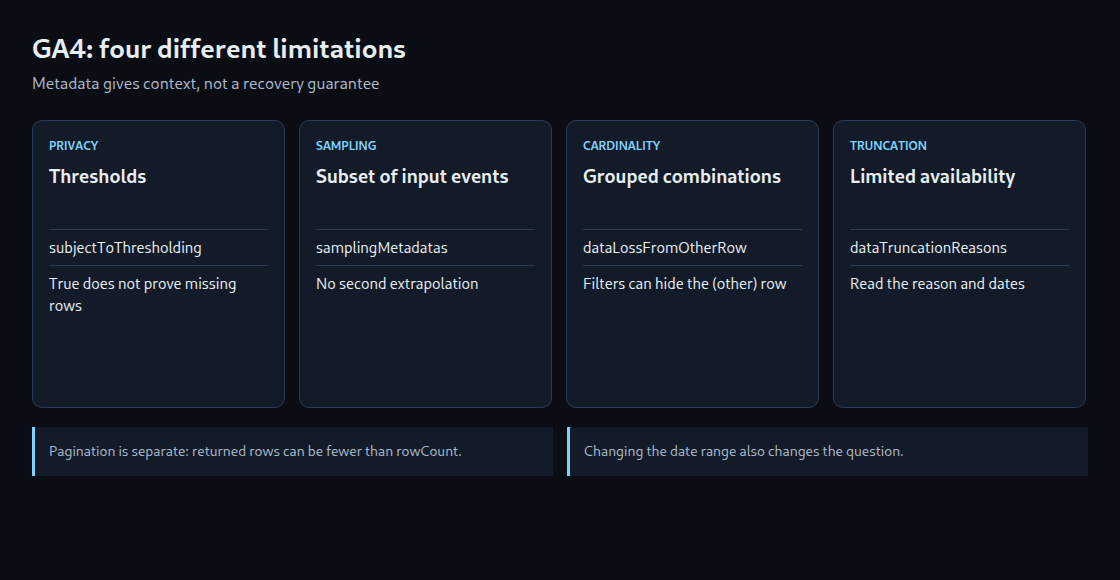
The diagram separates four possible report limitations. More than one can apply to the same response. A warning explains a reporting condition; it does not reconstruct hidden rows.
What privacy thresholds protect
Google applies system-defined thresholds to reduce the risk of identifying people or sensitive information. The documented cases include demographic data, audiences defined through demographics and search-query information. A small report is not automatically thresholded, and a detailed breakdown alone does not establish the cause of a missing row. The report’s quality indicator and response metadata provide a better starting point. [1]
Four mechanisms, four different questions
- Thresholding: does displaying a result require enough users to contribute to that result?
- Sampling: was the calculation based on a subset of events?
- Cardinality: were dimension combinations combined into
(other)? - Truncation: was part of the requested data unavailable, for example for a particular period?
Cardinality means the number of distinct values or combinations of dimension values. These conditions can coexist. A larger date range may help one question while changing the scope of another. A single badge labelled “data missing” would conceal the difference.
The 14 September 2026 API addition: reasons for truncation
The Data API metadata now includes dataTruncationReasons [8]. Each reason can carry a type, a message and affected dates. Those supplied dates are more useful than guessing which part of a long reporting period is available. The response also exposes sampling counts and active metric restrictions. [2]
{
  "metadata": {
    "subjectToThresholding": true,
    "dataTruncationReasons": [{
      "dataTruncationType": "DATA_TRUNCATION_TYPE_DATE_RANGE",
      "dataTruncationMessage": "Synthetic example",
      "dataTruncationDateRanges": [{
        "startDate": "2026-01-01",
        "endDate": "2026-01-31"
      }]
    }]
  }
}
This deliberately minimal example demonstrates the structure, not an actual API result. Crucially, subjectToThresholding: true does not prove that rows were withheld: every row may satisfy the threshold. Likewise, dataLossFromOtherRow can be true even when a filter hides the (other) row. [2]
A repeatable investigation
A useful investigation retains the request, date range, dimensions, filters and response together. Next comes a check of the metadata. If the number of returned rows is smaller than rowCount, request pagination deserves attention; that difference is not itself proof of sampling. A second request should change one relevant element at a time so that its effect remains interpretable. [4]
For example, an analysis involving demographic information might compare a longer period or a report without the sensitive dimension. The comparison answers a changed question and needs that qualification. Switching reporting identity should not be presented as a universal threshold-removal technique.
BigQuery provides a different dataset
The export supports analysis of raw events, but it does not reproduce every enrichment in GA4 reports. Google Signals data is not exported, and the export has availability, configuration and processing limits. Streaming is a best-effort feed. Consequently, “every event with every field is always available” is too broad a promise. Differences between the interface and an SQL result require a comparison of definitions and available data. [1, 3]
Using the response inspector
The linked inspector separates metadata findings from API quota information. Quota consumption describes the request budget, not the completeness of the report. A missing quota object is not a zero balance, and missing metadata is not a clean bill of health. The tool interprets the supplied JSON locally; it cannot inspect a property or confirm correct event collection.
Questions and answers
Does a longer date range restore missing rows?
It can increase the users contributing to an aggregate and reduce privacy suppression, but recovery is not guaranteed. With a date dimension, adding days still leaves separate daily rows; a larger overall population need not increase every row. The question also changes: a quarter does not describe the same period as a week.
More events can increase sampling pressure, and more distinct dimension combinations can increase cardinality. These are separate mechanisms, not inevitable results of extending the range. Event-data retention can limit explorations and funnel reports; standard aggregated reports are not governed by that same retention setting. Increasing retention does not restore data already deleted. [5, 6]
Does Device-based switch off privacy thresholds?
No universal bypass is documented. Device-based changes the identity used to count users; it is not a switch that removes Google Signals demographic data from every report. The current identity options use User-ID, device ID and, for Blended, modelling. A comparison must retain its changed identity definition, and the quality indicator still needs checking. [7]
Does a 30% sample mean that 70% of the displayed result is missing?
No. For example, 12,000 events read from a sampling space of 40,000 means a 30% input sample. GA4 uses sampled input to produce report estimates. Multiplying the returned metrics by 40,000 / 12,000 again would apply a second extrapolation. The ratio describes the calculation’s input, not a list of missing rows. [2, 5]
Related articles