English
 Deutsch
 Polski
Conversions API Hashing: Normalising Customer Parameters Before SHA-256 and Which Fields Stay Unhashed

Contents
A Conversions API event that carries a hashed email address looks the same whether the hashing was done right or wrong. The payload validates, the API answers with a success, the event counter goes up, and the match quality figure stays where it was – because the address, correctly hashed into a string that corresponds to nothing, was compared against a customer base and found in none of it.
That is the failure mode worth understanding before any of the plumbing: hashing does not fail loudly, it fails by producing something that is technically flawless and semantically empty.
Why a Small Difference Is a Total Difference
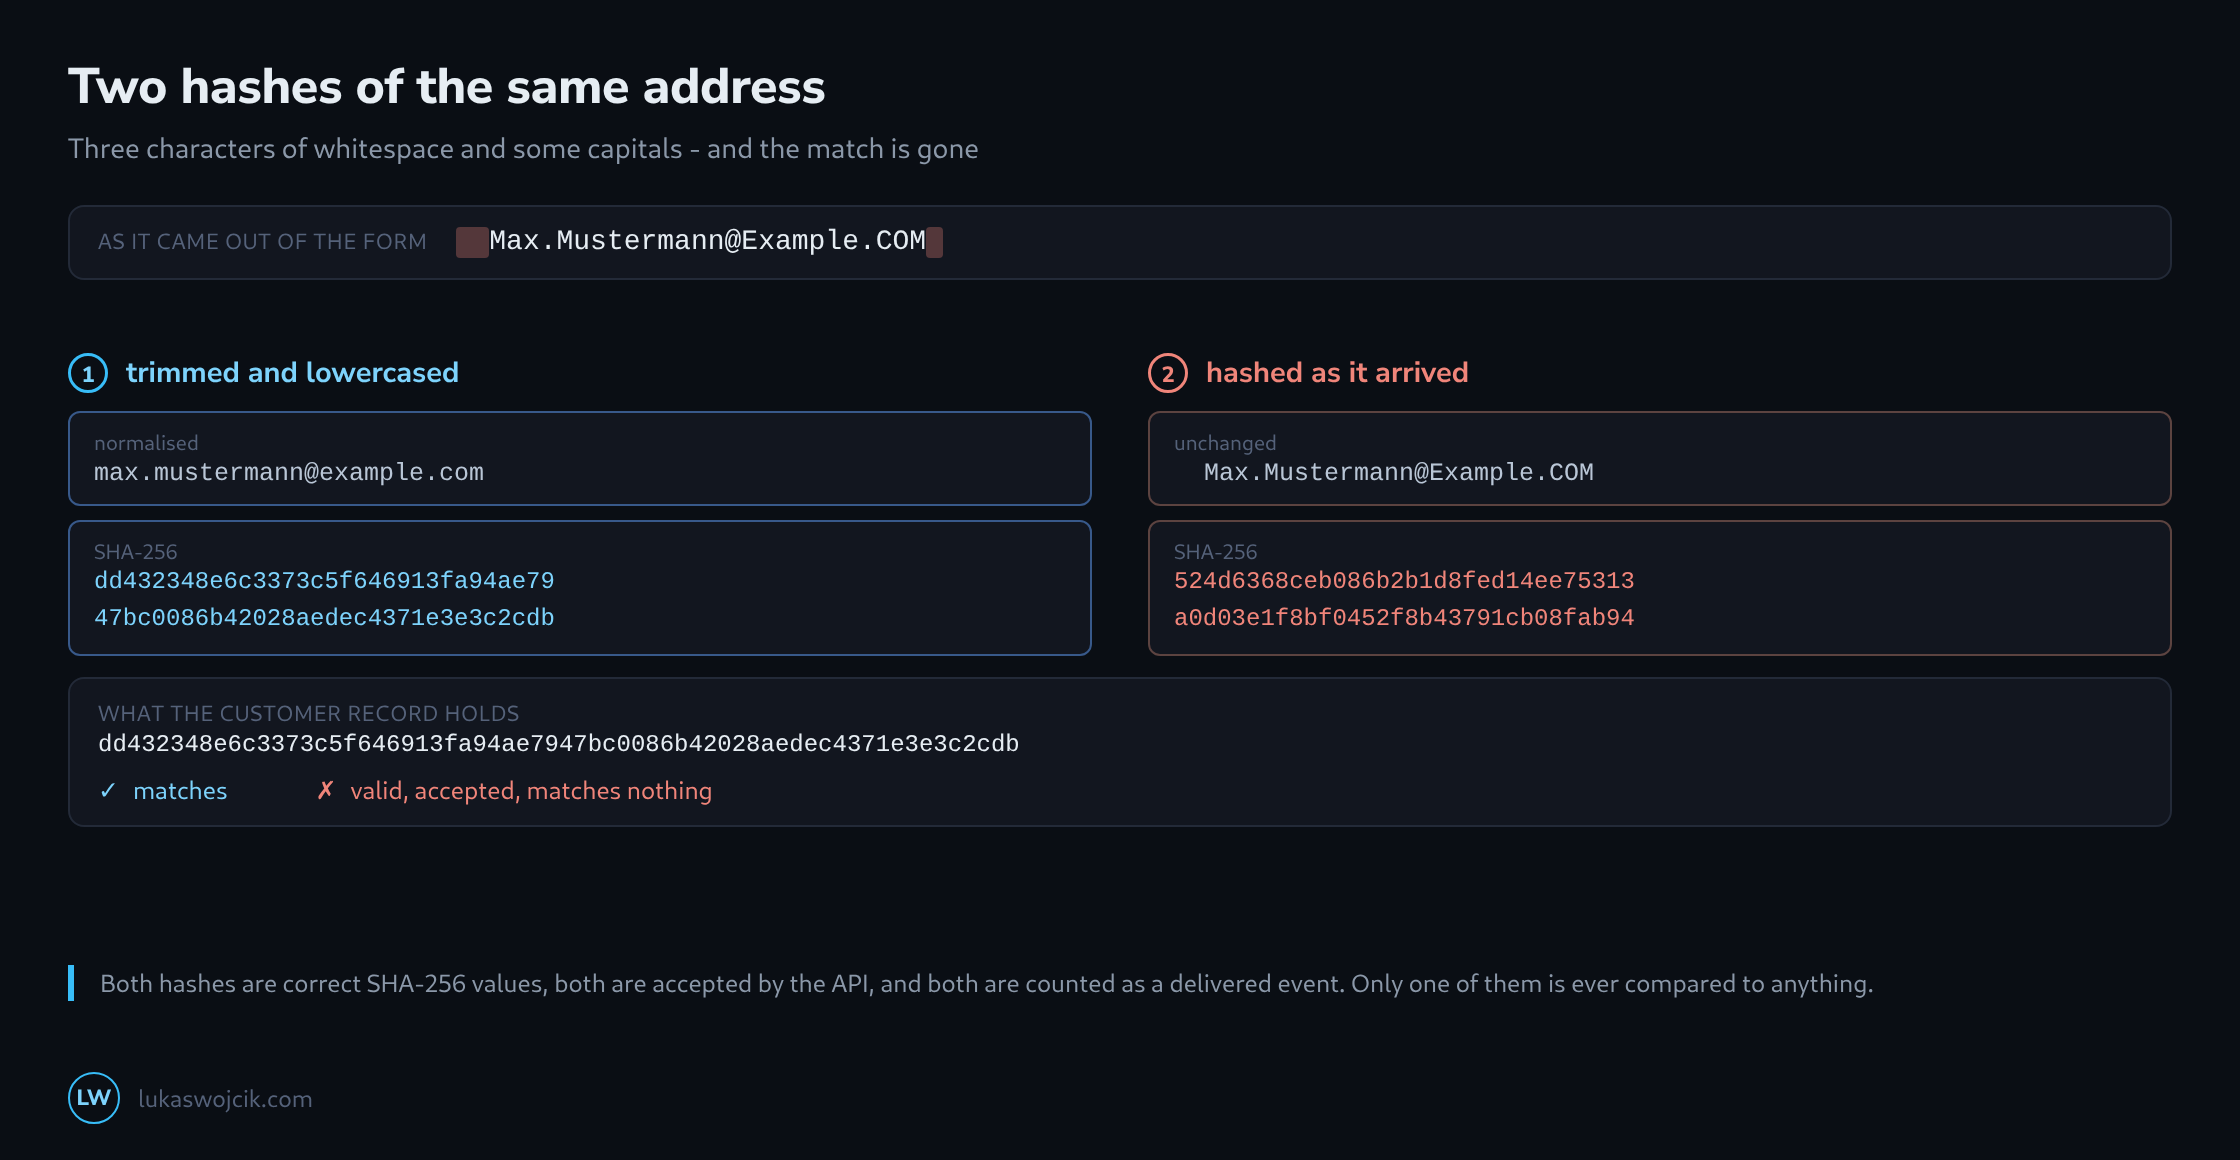
A hash function is built so that a minimal change to the input produces an unrecognisably different output. That property is what makes hashing useful, and it is exactly what makes a normalisation mistake fatal: there is no such thing as almost matching. Two hashes are identical or they have nothing to do with each other, and no amount of fuzzy matching downstream can recover the difference.
So the entire question of whether an event finds a person is decided before the hash function is ever called, in the few lines that decide what exactly goes into it.
The Form Each Parameter Has to Take
| Parameter | Required form | What goes wrong |
|---|---|---|
em |
trimmed, lowercase | a capital from the form, a trailing space from a paste |
ph |
digits only, with country code | the national trunk zero in +49 (0)170 survives |
fn, ln |
lowercase, no punctuation or spaces | a hyphen in a double-barrelled surname |
ct |
lowercase, no spaces | Frankfurt am Main keeps its spaces |
st, country |
two-letter lowercase code | the country is written out |
ge |
exactly f or m |
anything else, hashed as if it were a value |
db |
YYYYMMDD | a locale date format, silently reordered |
The phone number deserves a note of its own, because it is the one case that cannot be normalised mechanically. Stripping non-digits from +49 (0)170 1234567 leaves 4901701234567, and the zero after the country code is a national dialling prefix that has no place in an international number. No rule can decide that reliably for every country, which is why the honest handling is to strip, then flag the suspicious pattern for a human rather than guess.
The Parameters That Must Not Be Hashed
The opposite mistake is rarer and just as final. client_ip_address, client_user_agent, fbp and fbc are sent in plain text. They are not personal identifiers in the sense the hashed fields are; they are values Meta matches against its own records, and a hashed one is a string that corresponds to nothing on the other side.
This happens most often when a hashing helper is applied to the whole user-data object at once, which is a reasonable-looking piece of code and wrong in exactly four fields. A helper that hashes by field name rather than by object is the version that survives a schema change.
What This Looks Like From Outside
# the same address, three ways
"  Max.Mustermann@Example.COM "   → 524d6368ceb086b2b1d8fed14ee75313…
"  max.mustermann@example.com "   → de4c5edc5348280eedb5b029d7851764…
"max.mustermann@example.com"      → dd432348e6c3373c5f646913fa94ae79…

# only the third is ever compared against anything
None of these produces an error. The event count in the events manager is identical in all three cases, the delivery is confirmed in all three cases, and the only figure that moves is the match quality – downwards, slowly, in a way that is easy to attribute to seasonality or to a consent change.
Which is why the useful check is not the API response but a comparison against a known value. Take one address from the customer base, hash it the way the shop hashes it, hash it the way the specification prescribes, and compare the two strings. They match or the pipeline has a normalisation bug, and the answer takes a minute.
Where the Normalisation Belongs
The last decision is architectural. Normalisation can happen in the browser, in the server container, or in the backend that has the customer record – and only the last of those has the original value in the form the customer base stores it in.
Doing it in the server-side container is the common middle ground and works, provided the container receives the raw value and not something a form has already mangled. Doing it in the browser is the one arrangement to avoid: it puts the plain address into a request that leaves the visitor’s machine, which is precisely what the hashing was there to prevent.
Questions and answers
Does hashing make customer data anonymous under data protection law?
No. A hash that Meta can match against its own customer base is pseudonymised, not anonymous, and under the GDPR pseudonymised data remain personal data; linking the value to a person is in fact the whole purpose here. Hashing keeps the address from being transmitted in plain text, but it replaces neither the lawful basis nor consent.
What happens if a value is hashed twice on its way to Meta?
The same as with a normalisation mistake: the payload validates, the API reports success, and no person is found. A hash of a hash is again a string of 64 hexadecimal characters, so it looks like a correct one and still corresponds to no record on the other side.
The case arises where two stages each behave sensibly on their own. The shop system delivers the address to the server container already hashed, and a tag there hashes every user-data field once more. Neither stage is wrong in isolation; only the chain is.
The usual safeguard is a check before hashing: if a value already consists of exactly 64 characters from 0–9 and a–f, it is passed through instead of being hashed again. An email address never matches this pattern because it contains an @, and neither does a phone number, because E.164 allows at most 15 digits. The comparison against a known value that the article describes catches the rest, provided it is applied at the end of the chain, to the payload that actually goes to Meta, and not to an intermediate stage.
How should the postcode and external_id, which the table leaves out, be handled?
The postcode (zp) is hashed and, before that, written in lower case without spaces or hyphens: the Polish postcode 00-950 becomes 00950, the Dutch 1012 AB becomes 1012ab. For the United States, Meta asks for the first five digits only.
external_id is the shop’s own identifier, such as the customer number. Meta recommends hashing it but does not require it. What matters is consistency: if the identifier is also sent through the pixel, it has to arrive in the same form on both paths, hashed or not, because otherwise Meta sees two different identifiers.
Sources
Related articles